As Rebecca has noted, people are always asking those of us who teach about AI & the law some variation of, “How do you keep up with it all?” The real answer is long and not what most folks really want. So, here’s some advice. Just visit The Finite Scroll periodically. There. Done!
Too easy? Okay, you also need to vote up content you like (👍) and vote down (👎) content you don’t. If you don’t have a strong feeling and just want to clear out some content, mark it as “Seen.” And don’t worry, all of your votes live in your browser. The site doesn’t share them with anyone because it’s an open-source client-side algorithmically-driven RSS reader built at the Suffolk LIT Lab. By default the feed is tuned to return AI and law content. However, that focus will only hold until your preferences take over. Most importantly: you control the algo! Click “Settings” to fiddle with all the sliders you like. There are a lot of sliders.
If you find the default feed is a bit too “mainstream” for your liking, Rebecca’s list of resources for AI & law has you covered. That’s where you’ll find the deep cuts. But let’s make it easy. Click this link to load the AI Law Librarian Mix. Remember, this set of feeds leans a tad more technical than the default, and it doesn’t have the same general news coverage.
Regardless of where you start, you can always add new feeds. It is an RSS reader after all. Just hit the “+” button in the top right. You can also use the 🚫 icon at the bottom of a card to stop subscribing to a feed. Before you do this, however, I suggest clicking on the feed’s name to the left of 🚫. This will show you recent posts in the feed. Who knows, maybe you like some of what’s there and just need to aggressively vote down the ones you don’t like.
If 50 feeds (the rough size of the two starter lists above) strikes you as too small, I recommend clicking through to load the Fire Hose. It contains over 300 feeds (including the content of the AI Law Librarian and default feeds) ready for you to whittle them down into the perfect customized news experience. Maybe the Finite Scroll is your new homepage. It also works as a web app on your phone.
Did I mention you can bump or mute text? That’s right, if you never want to miss a post on AI Law Librarians, you can put “ailawlibrarians” under “Bump Up.” Never want to hear about a certain public figure? Place their name in “Mute.”
And that’s only some of what you can do under “Settings.” So, knock yourself out. Then tell all your friends. After all, using an RSS reader is “the one thing you can choose to do that will make your internet life better and make the internet better for everyone else, too.” Put another way, using an RSS reader lets you “escape newsletter inbox chaos and algorithmic surveillance by building your own enshittification-proof newspaper from the writers you already read.”
David is the Co-director of Suffolk University Law School’s Legal Innovation & Technology Lab. An attorney and educator by training, he has worked as a public defender, data scientist, software engineer, and high school physics teacher. He is the author of a programming language for lawyers, QnA Markup, an award winning legal hacker, ABA Legal Rebel, and Fastcase 50 honoree.
Three years ago, AI Law Librarians published a post on keeping up with generative AI in the law. People still ask me some version of that question all the time: how do you keep up? The truth is, I don’t keep up with everything, and I’ve stopped trying. What I have is a small set of sources I trust, a feed I’ve trained to show me AI and law, and a couple of communities where the best stuff surfaces on its own.
If you want a longer, filterable list, it’s here: Sources for following AI and law. This post is the short version: what I actually read now, and what’s changed.
What’s changed since 2023
I left Twitter. In 2023 it was still one of my main sources. I know a lot of AI conversation still happens on X, but I’m not on that platform. I’ve accepted that I’ll hear about some things a bit later, once they bubble up on LinkedIn, and that tradeoff is fine with me.
LinkedIn became my main feed. In 2023 I noted that legal tech discussions seemed to be moving there. They did, and now it’s where most of my day-to-day news comes from.
Some newsletters lasted; some didn’t. One Useful Thing, Lawyer Ex Machina, and The Brainyacts were on my 2023 list and are still on it. Others have gone quiet, been renamed, or just fallen out of my rotation.
Communities matter most. My 2023 post didn’t mention a single community. Now they’re where I learn the most (more on that below).
My top five
One Useful Thing (Ethan Mollick). If you read one general AI newsletter, make it this one. Practical, hands-on, and grounded in what the tools can actually do right now.
LawNext (Bob Ambrogi). Consistent, reliable reporting on legal tech and legal AI. When a legal AI product launches or changes, this is where I check.
Lawyer Ex Machina (Eli Edwards). Short and frequent, but not too frequent. A well-curated set of links on legal tech and AI in law.
The Brainyacts (Josh Kubicki). Longer and more frequent, with lots of experiments. Good if you want to see someone actually trying things.
Legaltech Hub. Much of it is paid, but a generous amount is free, including articles and a legal tech directory. Following their people on LinkedIn, like Stephanie Wilkins and Sarah Glassmeyer, often gets you free excerpts of the paid pieces, too.
Building a balanced feed
LinkedIn works for me not because it’s great, but because I’ve trained my feed. I follow broadly, I engage with posts that teach me something, and I mute the hype and people who post about things I don’t need to know (sorry to my former bankruptcy colleagues). After a while the algorithm gets the message.
The trick is balance. If everyone you follow is a booster, you’ll think every problem is solved; if everyone is a skeptic, you’ll miss what’s genuinely useful. So I try to make sure my feed has a mix: people who experiment with the tools and show their work, skeptics who check claims against the evidence, people tracking what goes wrong (like hallucinated citations in court filings), information literacy folks who teach you how to evaluate what AI gives you, voices on ethics and AI’s broader costs, and legal innovators rethinking how legal work and legal education get done.
Here are a few of the people I learn from. It’s not a “best of” list, just a starting point:
Ethan Mollick, for frequent, practical experiments between newsletter issues.
Mary Matuszak and Kyle Bahr, also for hallucinations, and for the legal practice view of what’s going wrong and why.
Mike Caulfield, creator of SIFT, for information literacy and critical reasoning with AI.
Sasha Luccioni, for AI’s environmental costs and what sustainable AI could look like.
Casey Fiesler, for accessible AI ethics. She’s also very active on Bluesky and TikTok.
Cat Moon, for legal innovation and rethinking how lawyers learn and work with AI.
Jenny Wondracek, for a law librarian’s view of AI in legal research and legal education.
If you post thoughtfully about AI and law and I’m not following you, tell me.
Where my best news actually comes from: people
Newsletters and feeds aren’t where I learn the most. That happens in a couple of communities: LegalQuants, a network of lawyers who build their own AI tools, and a private Discord server for law librarians interested in AI. Someone always spots the new case, the new tool, or the new paper before I do, and the discussion around it (including members’ own experiments and use cases) is often more useful than the item itself.
Both are invite-only, and that’s part of why they work. In a small group of people who trust each other, folks share half-formed thoughts and new finds freely, and nobody is performing for an audience. (LegalQuants isn’t completely closed: one way in is through its AI Residency.)
So my biggest recommendation is to find your own people. A few places to start:
If you’re a law student, find (or start) an AI and law student group at your school. Names vary: Law & Technology Society, Legal Innovation Society, AI & Law Society. Legal Hackers also supports student groups.
If you’re a practitioner, look for a local Legal Hackers chapter. They’re free, open to anyone, and host public events in cities around the world.
If you’re a librarian, your professional association’s special interest sections and listservs are a good place to find others working on this.
Wherever you are, look for the Slack, Discord, or listserv where your peers already talk about AI. And if there isn’t one, start it! That’s what a few colleagues and I did with our Discord group.
Don’t try to follow everything
Pick one dependable general source and one source tied to your own field. Build a habit you can actually keep. Then add people and communities over time. You’ll miss things. Everyone does. The things that matter tend to come around more than once.
What did I miss? What’s the one source, person, or community you’d never give up? Tell me in the comments. Despite telling you to curate your sources, I’m personally always looking to widen my net. (I’ll curate someday, I promise.)
A few weeks ago I finally made a personal website, and I’ve been gradually putting things up there. It started as something I made mostly for myself (kind of like how I’m the primary user for most of my favorite LibGuides I’ve created). But there are now two resources that I think will be useful to readers of this blog, whether you’re teaching an AI or legal tech course, helping faculty who are, or just looking for something to read or circulate to colleagues.
The AI in legal practice textbook explorer
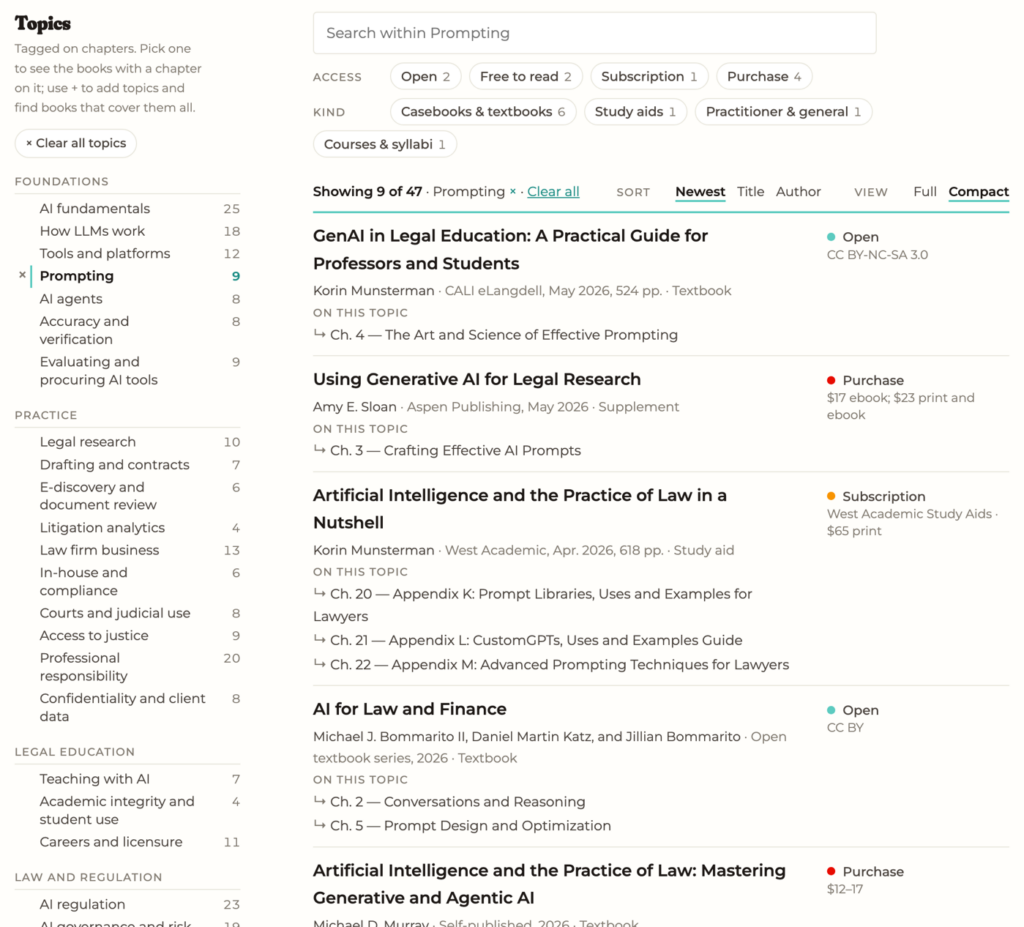
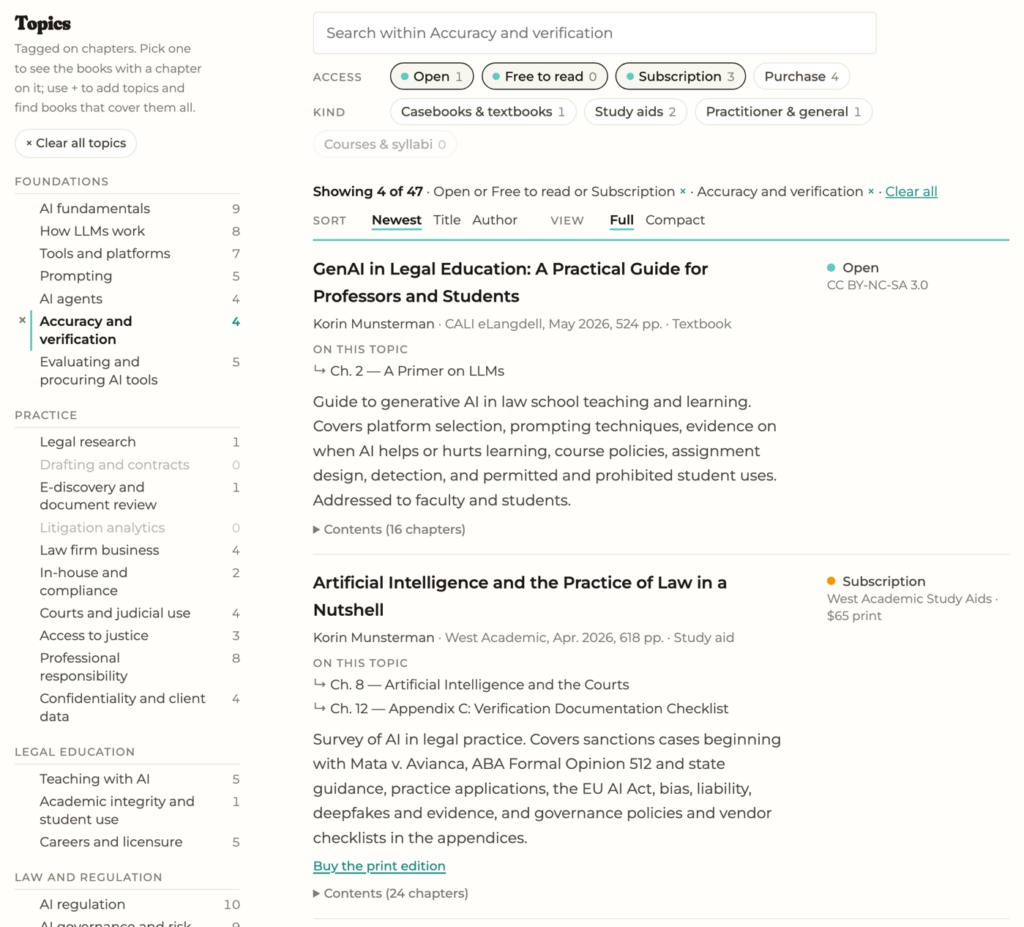
Books and teaching resources on AI in legal practice collects 47 textbooks, casebooks, study aids, practitioner books, and open materials. For most of them, I’ve added the table of contents with each chapter tagged by topic. That means you can pick a topic, like prompting or hallucinations, and get the specific chapters that cover it, not just a list of titles.
You can also filter by how you’d get the book. If I’m just assigning a chapter, I usually want only the open, free, and typically licensed titles (several are in the West Academic Study Aids package many academic law libraries already subscribe to). Or you can go the other way and look for one book to purchase that covers everything you want. You can combine topics, search chapter titles, and share a link to exactly the filtered view you’re looking at.
My 21st Century Lawyering reading list
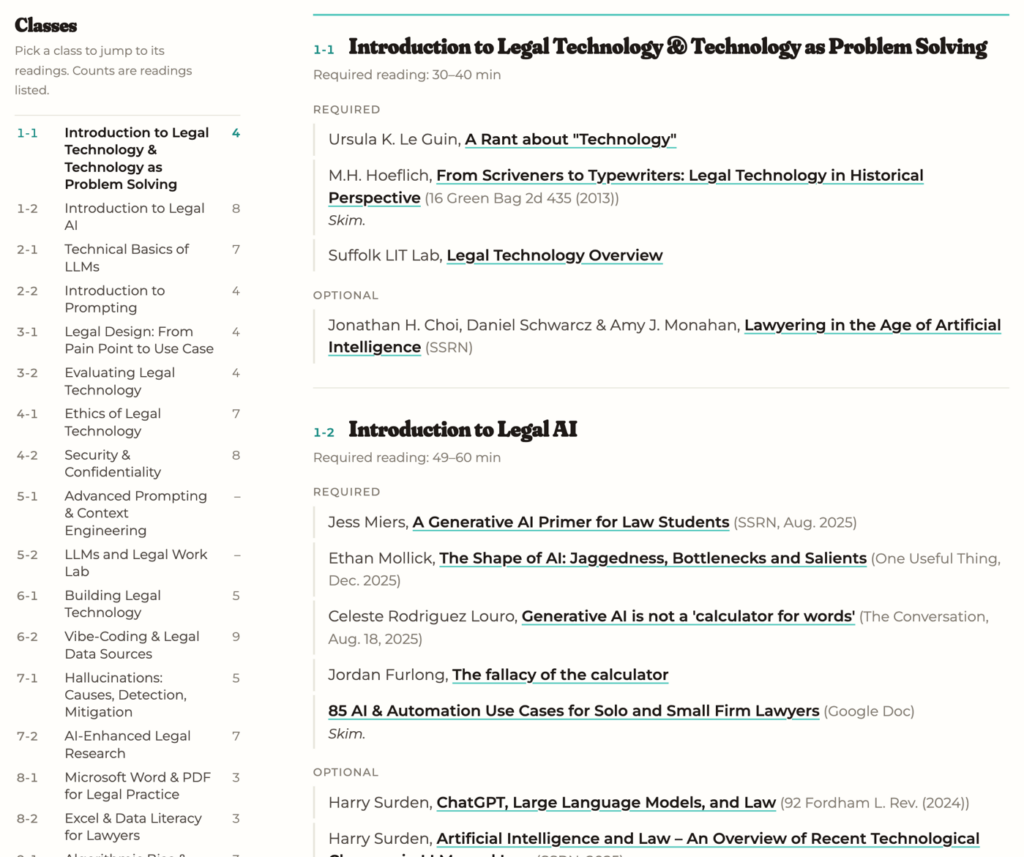
I’ve also posted the full reading list from my AI/legal tech class this spring, class by class. It covers 26 classes and 100+ readings, from LLM basics to vibe-coding to access to justice, with required and optional readings marked and the time estimates I gave students. These are fast-moving topics, so some of it may need updating, but most of it should still be relevant in a year (I hope!).
Feel free to borrow anything. And if you know of a book I’ve missed, or a reading that worked well in your class, please let me know. I plan on keeping the book list updated, and posting new class reading lists in future years.
AI may have struck again with hallucinations. Yesterday evening, I was forwarded a quote from the case opinion of Shahid v. Esaam, 2025 Ga. App. LEXIS 299, at *3 [Ct App June 30, 2025, No. A25A0196]) released on June 30, 2025 by the Georgia Court of Appeals. (HT Mary Matuszak!)(link to official opinion, not Lexis):
We are troubled by the citation of bogus cases in the trial court’s order. As the reviewing court, we make no findings of fact as to how this impropriety occurred, observing only that the order purports to have been prepared by Husband’s attorney, Diana Lynch. We further note that Lynch had cited the two fictitious cases that made it into the trial court’s order in Husband’s response to the petition to reopen, and she cited additional fake cases both in that Response and in the Appellee’s Brief filed in this Court.
Background
The Georgia Court of Appeals (CoA) heard an appeal to reopen a divorce case in the Superior Court of Dekalb County, GA. The Appellant brought to the attention of the CoA that the “trial court relied on two fictitious cases in its order denying her petition.” The Appellee’s attorney ignored this claim and went on to argue the original argument of proper service by publication with multiple fictitious and misrepresented cases. The Appellee’s attorney also demanded attorney’s fees based on another fictitious case that claimed the exact opposite of existing case law. In total, the CoA provided this breakdown of the inaccuracy rate of the citations provided by the Appellant’s attorney, “73 percent of the 15 citations in the brief or 83 percent if the two bogus citations in the superior court’s opinion and the five additional bogus citations in Husband’s response to Wife’s petition to reopen Case are included.” The distraught CoA struck the lower court order, remanded the case, and sanctioned the Appellee’s attorney.
Digging into the Case
I was curious about all of this, so I did some digging this morning. I am still working on acquiring the CoA briefs, but I was able to access the documents from the trial court. The CoA was very cognizant that they do not have any actual proof at this time that AI was used, but with the number of bad citations that the Appellant’s attorney submitted, the CoA speculated about the use of a consumer AI model in the footnotes. To test this theory, I decided not only to do some reading, but to test out LawDroid’s new CiteCheck AI tool. Spoiler alert: I think the speculations are accurate.
CiteCheck AI
If you have not yet heard of LawDroid’s new CiteCheck AI tool, that is only because it is so new. The premise of this tool is you upload a document, and it will check your case citations to see if the citations exist (a.k.a. identify hallucinations). The free version gives you the ability to test it out with five documents. It will OCR your document (if needed), extract the citations, and check the citations against the CourtListener database. You are then given a nice table of the citations, marking them as valid or invalid. If the latter, you are also supplied the reason why it is marked invalid. Remember, however, this only checks their existence, not whether they stand for the proposition for which they are being used.
Bob Ambrogi posted a review of the application that he tested with the Mata v. Avianca, Inc.documents and a document he filed when in practice. From this review, I knew to expect a few false “invalid” markings if the case only has a Lexis or Westlaw citation or if there are abbreviation issues with the case citation. Bob noted that these issues were relatively easy to spot since CiteCheck AI lists the reason it marked the citation invalid.
The CiteCheck AI website also reminds attorneys that you still need to meet your ethical obligations and review everything before submitting it: “Disclaimer: CiteCheck AI is only a tool, it does not relieve lawyers from their duty of care, supervision, and competence. Ensure that you carefully review all work product before sharing it with clients and/or filing it in court.”
The Trial Order
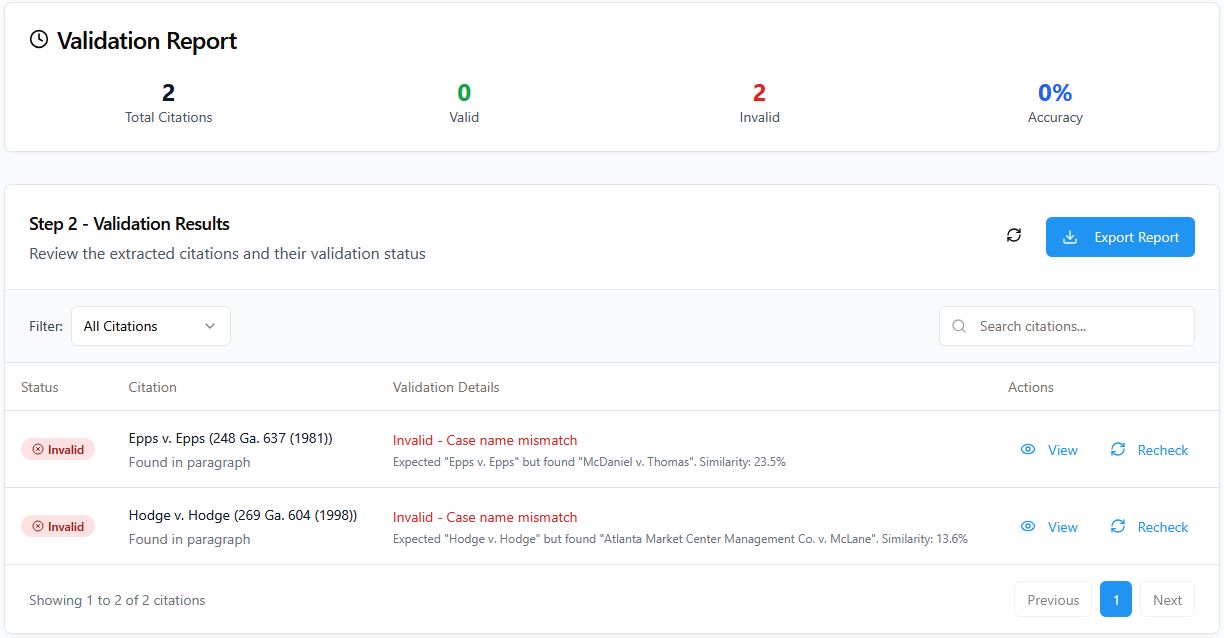
I decided to start with the Trial Order as it is truly the most momentous document here, given it is the first known court order with “bogus” citations, as the CoA called them. The CoA specifically mentioned “the bogus Epps and Hodge case citations from the superior court’s order” in footnote 24, so I went in knowing what cases to watch out for. It turns out that these were the only two cases mentioned in the order, making them really easy to locate.
The first case was listed as “Epps v. Epps (248 Ga. 637,285 S.E.2d 180, 1981)” and was supposed to discuss service by publication. When I ran 248 Ga. 637 through Lexis, it led me to school financing case McDaniel v. Thomas, 248 Ga. 632, 632, 285 S.E.2d 156, 157 (1981) (note the different SE2d reporter citation!). Curious to see what the Epps parallel citation 285 S.E.2d 180 would lead me to, I found criminal case Lewis v. State, 248 Ga. 566, 566, 285 S.E.2d 179, 180 (1981). No sign of Epps v. Epps.
Next, I tried searching the parties. Epps v. Epps, restricted to Georgia cases, returned three results: 1. Epps v. Epps, 162 Ga. 126, 132 S.E. 644 (1926)(Sufficiency of the Evidence) 2. Epps v. Epps, 209 Ga. 643, 644, 75 S.E.2d 165, 167 (1953)(Implied Trusts) 3. Epps v. Epps, 141 Ga. App. 659, 659, 234 S.E.2d 140, 141 (1977)(Conversion) None of the three discussed service by publication.
The second case was “Hodge v. Hodge (269 Ga. 604,501 S.E.2d 169, 1998),” another alleged service by publication case. Here is the breakdown of this case:
269 Ga. 604 led to fiduciary Atlanta Mkt. Ctr. Mgmt. Co. v. McLane, 269 Ga. 604, 503 S.E.2d 278 (1998)(agency, fiduciary obligations, and contracts)
501 S.E.2d 169 led to the middle of Foster v. City of Keyser, 202 W. Va. 1, 501 S.E.2d 165 (1997)(res ipsa loquitur)(Not even the same state!)
Hodge v. Hodge search led to a divorce case! But no mention of service by publication in divorce: Hodge v. Hodge, 2017 Ga. Super. LEXIS 2178.
Trial Order – CiteCheck AI Review
Now that I have done the work by hand, how did Citecheck AI compare?
Success! We both found the same cases for the Georgia reporter cases. It did not check the parallel Southeastern Reporter citations, however. It definitely took a lot less time (under a minute) for CiteCheck AI than it did for me going through all four reporter citations in Lexis.
The Trial Response
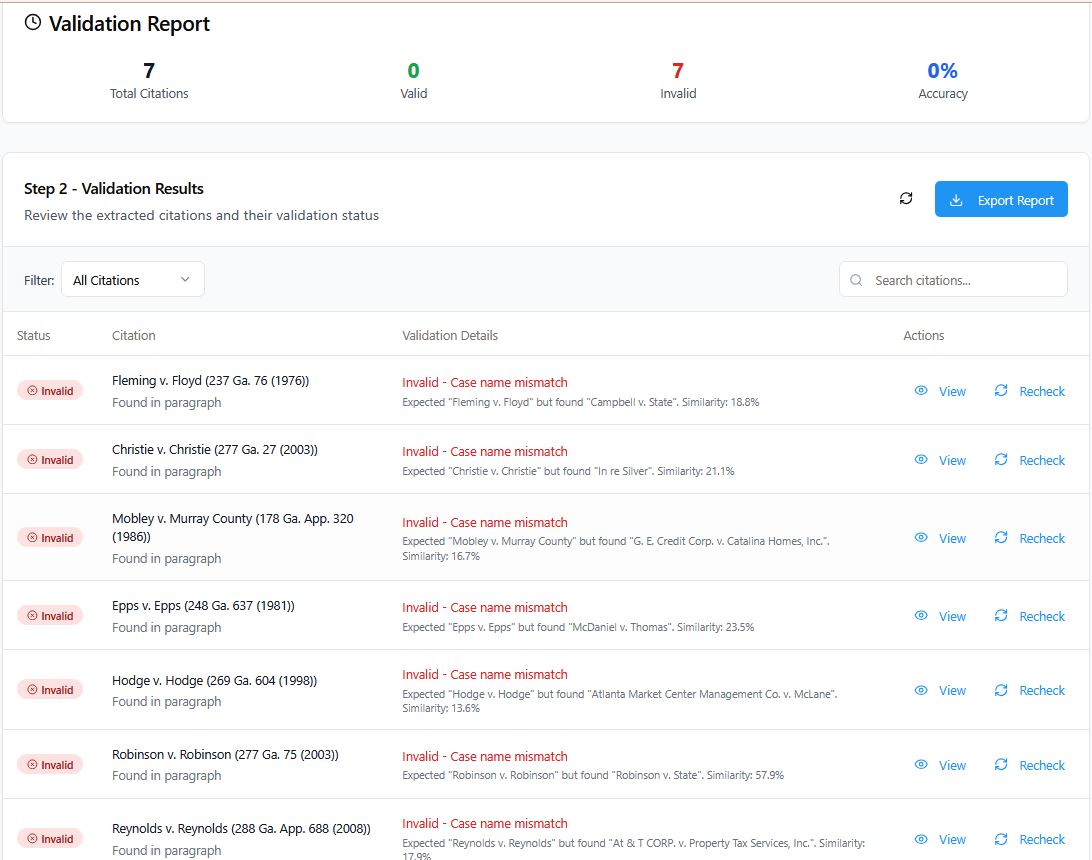
Per the CoA, I expected to find seven total bad citations in the Response, including the Epps and Hodge citations that I reviewed above. Being a good (and nosy) librarian, I went through both the Georgia and the Southeastern Reporter citations for each citation, if provided. Liking the CiteCheck AI tabular format, I provide you with my own results in similar style:
And success again! CiteCheck AI found the same cases that I did with a manual check for the Georgia reporter citations. Parallel citations once again were not considered, however (given the Bluebook no longer requires them, this may not be an issue for long). A new hiccup to take note of, however: It did not report that two cases were located with the Christie v. Christie Georgia reporter search. While page 27 is supposed to be the first page in the citation, it is not unheard of for a student or attorney to put the page number of the language they refer to instead. This makes me uneasy, and I hope this is on the improvement list to include both/all cases on the page listed.
Takeaways
From this exercise, I take a few key lessons and thoughts.
The inevitable has happened, and a court has issued an opinion with hallucinated cases.
The Court of Appeals did not investigate how the hallucinated citations were put into the order, but I am sure someone will. I await the final report.
Give the disciplinary case that I read from the Christie v. Christie search, Georgia takes this sort of thing seriously. The Appellant attorney may face more than just sanctions in the future.
The Citecheck AI tool is useful, as long as you remember its limitations.
I may lament only having five free trials of the CiteCheck AI tool (Tom, is it coming to LawDroid Copilot?)
I now fear the day another order is not caught and hallucinations become law.
I had the pleasure of co-teaching AI and the Practice of Law with Kenton Brice last semester at OU Law. It was an incredible experience. When we met to think through how we would teach this course, we agreed on one crucial component: We wanted the students to get a lot of reps using AI throughout the entire course.
That is fairly easy to accomplish for things like research, drafting, and general studying for the course but we hit a roadblock with the assessment component. I thought about it for a week and said, “Kenton, what if we created an AI that would Socratically quiz the students on the readings each week?” His response was, “Do you think you can do that?” I said, “I don’t know but I’ll give it a try.” 🤷♂️
Thus Socratic Quizbot was born. If you follow me on social media, you’ve probably seen me soliciting feedback on the paper:
I'm no longer a teacher. I'm just a human plagiarism detector.
I used to spend my grading time giving comments for improving writing skills. Now most of that time is just checking to see if a student wrote their own paper. What a waste of life.
A lot of the motivation for Quizbot was a new paradigm in the law school ecosystem: the take-home essay is effectively dead. In fact, lots of the typical homework that you would assign as a law school professor simply breaks when you introduce something like ChatGPT or Claude into our world. We needed to come up with new methods of assessment.
I knew that these tools were really good at ingesting documents like PDFs and then summarizing them (manipulating the text, generating based on the text, etc.). What I needed was an AI that could read our course readings and then have a back-and-forth Socratic conversation with the students about those readings, and then some method to assess those conversations so that I could give students a grade. This felt like a big task with many potential pitfalls for one guy who is only mediocre (at best) at coding and app development.
As it turned out, I was able to fumble my way through the process and create a method of assessment that students seemed to enjoy. Alright, “enjoy” is probably too strong of a word, but they tolerated it and said they liked it quite a bit more than something like a multiple-choice test or a take-home essay. The Socratic Quizbot enables you to scale cold-calling to every student in the class while eliminating much of the stress and embarrassment that law students have dreaded since time immemorial.
Since many of the people who are interested in this blog post may have already read or skimmed my article, I decided to add my update as Appendix A so that you could simply fast-forward to the portion that is relevant to you. There is also a link to the open-source code in Github.
Appendix A was born out of one question I kept getting after sharing the pre-print of my article: “How?” So, let me show you exactly how you can implement the Socratic Quizbot in your classroom, along with some insights from my students who graciously let me experiment with them.
Student Feedback, Challenges, and Improvements Students overwhelmingly preferred this method to essays or multiple-choice quizzes, citing the flexibility to ask for clarification and control the pace of their learning. It also reduced the fear of being judged by their peers. That said, a few students tried to game the system by flipping the questions back on the bot. My grading rubric handled that, but I’d like to make Quizbot more persistent in pressing them for answers next time. I’m also excited to explore gamification—adding themes, Easter eggs, or playful interactions to make the experience even more enjoyable.
Two Ways to Get Started If you want to try this yourself, you’ve got two paths. The no-code approach uses ChatGPT Teams and involves setting up a CustomGPT that ingests your course readings and quizzes your students. This is great if you’re looking for quick implementation. For the more tech-savvy or budget-conscious, the code-based option lets you host Quizbot locally using the instructions I’ve shared on GitHub. It takes a bit more effort but gives you total control over security and functionality. Hopefully you will see a version of Socratic Quizbot available in CALI.org in the future because I have been talking with John and Elmer and they both seem interested with integrating it into the platform (although, do not hold them to that because it’s still very-early talks).
Ultimately, my goal is to make this tool accessible for anyone in legal education. Whether you’re a tech whiz or new to AI, there’s a way to incorporate this into your classroom. And if you’re as curious about alternative assessments as I am, I’d love to hear your thoughts and ideas! The benefit of making it open in Github is that you can fork and improve my prototype. I would be deeply honored to see improvements on my little project and love to see what our community can do to improve it.
Today’s guest post comes from the University of Denver Sturm College of Law’s John Bliss. Professor Bliss has been kind enough to share some resources that he has crafted to help teach AI to lawyers and law students. In addition, he has launched a new blog which would likely be of interest to our audience so we are happy to host this cross-over event.
Teaching
I recently posted to SSRN a forthcoming article on Teaching Law in the Age of Generative AI, which draws from early experiments with AI-integrated law teaching, surveys of law students and faculty, and the vast new literature on teaching with generative AI across educational contexts. I outline a set of considerations to weigh when deciding how to incorporate this tech in the legal curriculum. And I suggest classroom exercises, assignments, and policies. See https://papers.ssrn.com/sol3/papers.cfm?abstract_id=4682456.
Blog
I’m also organizing a blog that provides up-to-date analysis of research on AI’s legal capabilities. You can subscribe at http://ai-lawyering.blog. Let me know if you’re interested in contributing. The motivation for the blog is that legal AI is a fast-moving field. It is all too common that our discussions are based on outdated and inaccurate information. Empirical findings are often misconstrued in mass and social media. The blog aims to address this issue by reviewing the latest high-quality research, emphasizing empirical studies of AI capabilities as well as scholarship on the implications of this technology for lawyers and other stakeholders in the legal system.
New Program on Generative AI for Legal Practitioners
I’m working with a non-profit teaching lawyers and other members of the legal profession about generative AI: http://oak-academy.org. Just last week, we held our first session with a group of lawyers, law students, and academics. It seemed to go well!
I look forward to continuing conversations on these topics. Please feel free to reach out—jbliss@law.du.edu
Vincent is vLex’s response to implementing AI into legal research and it’s the most impressive one that I’ve seen for legal research. Damien Riehl was kind enough to give us a personalized demonstration (thanks for setting that up, Jenny!) and it was a real treat to be able to ask questions about it in real-time. I would say that the best way to see this in action is to schedule a demo for yourself but if you want to hear my hot-takes about the platform, please keep reading.
Vincent is Really Cool
Interface
Many times when you engage with these models they feel like a complete black-box. You put in some text, 🪄 presto-chango 🪄, and then it spits something back to you that seems related to what you put into it. Vincent instead offers you a fairly controlled interface that is centered around what you typically need for something like real-world legal research. That’s because this doesn’t look like a “chatbot,” sandbox-type experience and feels more like a tool that a professional would use.
You Can Tell Where It Gets the Information
This is huge because almost everything you need is on one page immediately. You ask it to draft a legal research memo and the cases are just to the right of the memo. The relevant portions of the cases have been summarized and presented there for you. A tool tells you how confident Vincent is that this is close to your request. Everything below 70% is dropped. You can toggle between cases, regs, statutes, and secondary materials available. Everything that could require a deeper dive has a hyperlink. You can get a sense of what this looks like from vLex’s website about Vincent here: https://vlex.com/vincent-ai.
Multi-Stage Prompting
vLex is probably best known for its deep archive of primary international materials. Vincent uses this to great effect (since we know that many of these NLP technologies started as translation tools). You can enter a natural language question in English, Vincent will translate it, run the search in the home country’s language, and then provide you with both the original text (so you could translate it yourself) and an English (or whatever) language translation. Sexy stuff for you FCIL researchers. Also, this is substantially more powerful than something that simply tries to grind through many iterations of similar keyword searches in other languages.
It’s also a noteable example of multistage prompting and retrieval in legal research. You can see that it is being fed through not one prompt but many complex chains to produce high-quality, useful output. The tools for US caselaw are similar: Your query is turned into several different prompts that run off in different directions through the vLex database to retrieve information. Some prompts are searching through cases, statutes, regs and their secondary materials to see what is useful; others might be summarizing cases as they relate to your query; other prompts are finding counterarguments; another prompt is evaluating them for confidence on the your specific subject etc. etc. and a final prompt is summarizing all of this information into a neat little report for you. In summary, they’re making great use of the technology’s potential by deploying it in many different ways. The final product is sort of a fabricated, personalized secondary source created by running tons of prompts over the underlying primary materials. In fact, Damien calls this a “Me-tise” 😂 (apologies to Damien if I stole his punchline) and he foresees it being a powerful new tool for legal researchers. I’ve been bullish on the fabrication of secondary materials since I first saw what these things could do so it was exciting to see a precursor of this in action.
Damien let us know that behind the scenes they are using a combination of the various LLM’s to achieve these results and cut costs when possible: Claude, Llama2 (Meta), and GPT4. We met with him shortly after the OpenAI controversy and he pointed out that they are able to swap models in vLex if necessary.
Secondary Materials and Market Share
We have all come to love and rely on specific secondary materials that exist in Westlaw and Lexis. vLex’s acquisition of Fastcase meant that they acquired a huge, fantastic database of primary US materials. The one pain point for people who may be interested in switching from Westlaw/Lexis to Fastcase was the relative dearth of secondary materials available. The features that I saw last week in vLex may fill that need for some users and it will be interesting to see if people are lured away from their favorite practice guide or treatise published by Lexis or Thomson Reuters because a robot can now do some of that work summarizing and analyzing vast quantities of primary law. It will also be interesting to see if Lexis and Westlaw will roll out these types of features, since they could be in direct competition with their robust (and pricey) secondary materials offerings.
Before I get a slew of angry emails: I recognize that a traditional secondary material does much more than summarize cases, statutes, and regulations but it does some of that (also remember we’re still in the infancy of this technology for legal research). If that is all the researcher needs, then these tools could work as a replacement for some people (and they don’t rely on monthly updates – they do this on demand). That may allow some people to cut ties from Lexis and Westlaw in a way that could shake up the industry in a way that disrupts the status quo. It could also be incredibly powerful for something like a 50-state survey or even surveys across many different countries. Feel free to let me know what an ignoramus I am in the comments if I am missing something here.
Outstanding Questions
Price
I’ll dive right in where you all have questions, “Can we afford this thing?” Dunno and it depends (super satisfying, I know). The difficulty here is that these things are still very expensive to operate. The more sophisticated the model, the larger the database, the more complex the stages of prompting, the various modalities (scanning documents, reading the screen, etc.) – the more it costs them. They are all trying to figure out how to create a pricing structure where they can 1) offer it to the widest audience possible and 2) remain profitable. As we know, their primary source of revenue is the big firms and so the product is currently only available in paid beta for select companies.
Damien and vLex are both refreshingly upfront and clear about this. No hand-waving or sales talk, which I think is why so many people in our industry look to people like Damien for information about these technologies as they are developed. Damien mentioned that they are taking the “democratize the law” call to action from Fastcase seriously and are looking for ways to make it affordable on the academic market.
Possible Future Options
This is all complete speculation on my part but some sort of limited version of the platform seems like it could be reasonable for the academic market (like BLaw does with their dockets): limited uses per day, limited uses per account, a “lesser” account with limited features, etc. As the market stands today academic law libraries have access to a limited version of Lexis AI, trial access to Casetext Cocounsel (unless you’re willing to pay), no access to Westlaw Copilot, no access to Harvey AI, and no access to vLex. I anticipate all of that will change as the prices come down. The point of frustration is obviously that we want to be able to evaluate these tools so that we can teach them to students, in addition to using them ourselves so that we can benefit from the technology.
In conclusion, Vincent by vLex represents a significant step forward in AI-driven legal research. Its sophisticated multi-stage prompting, transparent sourcing, and potential in fabricating secondary materials make it a formidable tool. The future of Vincent and similar AI platforms in the academic and broader legal research community is certainly something to watch closely.
The pace of generative AI development (and hype) over the past year has been intense, and difficult even for us experienced librarians, masters of information that we are, to follow. Not only is there a constant stream of new products, but also new academic papers, blog posts, newsletters, and more, from people evaluating, experimenting with, and critiquing those products. With that in mind, I’m sharing my favorites, and I’ll also pepper in a few recommendations from my co-bloggers.
Twitter
Before Twitter began its slow decline, it was one of my primary sources for professional connection, and there are many there who are exploring generative AI. I especially enjoy following people outside of the legal world. Many of my favorites are still there, like Ethan Mollick, Anna Mills, and Lance Eaton (all in higher education) as well as critical AI theorists like Timnit Gibru and Emily Bender.
LinkedIn
Despite the good bits that remain on Twitter, many interesting legal tech discussions seem to have moved to LinkedIn (or perhaps I’ve only recently found them there). Some of my favorites to follow on LinkedIn (in no particular order beyond how I’m running across them as I scroll) are: Nicole Black, Sam Harden, Alex Smith, Cat Moon, Damien Riehl, Dennis Kennedy, Uwais Iqbal, Ivy Grey, Robert Ambrogi, Cat Casey, Nicola Shaver, Adam Ziegler, and Michael Bommarito. Both Bob Ambrogi and Nicola Shaver recently had posts gathering legal tech luminaries to follow, so I would recommend checking out thoseposts and the comments to find more interesting folks. And if anyone else has figured out the LinkedIn etiquette for connecting vs. following someone you only know via other social media, please let me know.
Newsletters
Most of us have many (many, many) newsletters filling our inbox each day. Here are some favorites.
Lawyer Ex Machina – from law librarian Eli Edwards, on legal technology, law practice and selected issues around big data, artificial intelligence, blockchain, social media and more affecting both the substance and the business of law (weekly)
The Brainyacts – from Josh Kubicki, insight & tips on generative AI use in legal services (daily)
Rebecca:
One Useful Thing – from Ethan Mollick, mostly on AI in higher ed (weekly)
Do Something – from Sam Harden, on legal tech, often from a small firm and access to justice angle
Legal Tech Trends – legal tech links, podcast, articles, products, along with original pieces (every two weeks or so)
KnowItAALL – this daily newsletters is a benefit for members of AALL (American Association of Law Libraries), but it is also available to non-members for a fee; great coverage of legal AI, I read it every day
AI Law Librarians – is it gauche to recommend our own blog? You can subscribe as a newsletter if you like!
Sean:
The Run Down – AI news, tools and tutorials (daily)
The Algorithmic Bridge – in-depth pieces about AI news, thoughts, and research every Monday, Wednesday, and Friday.
The Gradient Pub – accessible but technically informed overviews of the state of the art and its future, and critical and well-informed perspectives on artificial intelligence topics by researchers and experts in the field.
AI Lawyer Talking Tech (Sarah) – created by law librarian Greg Lambert, this podcast is completely AI-generated, and covers legal tech, with many stories on generative AI; it also links to a daily roundup of news articles
Chronicle of Higher Education ($) (Rebecca) – lots of work happening here on how generative AI will impact education (I like to search within for “ChatGPT”); you can also sign up for a daily update with headlines and trending stories
3 Geeks and a Law Blog (Rebecca) – many law librarian contributors, and they frequently blog about AI
Geeky Gadgets (Jenny) – a technology news site that publishes a lot on AI, including “how to use” articles
MIT News (Jenny) – general technology news on a wide variety of issues. AI shows up regularly. More technical, so may need to look at subtypes of AI, like machine learning
TechCrunch (Jenny) – often where I see developments break first
Unite AI – AI news aggregator. Some articles are on the technie side
Sean also mentioned that much of the interesting stuff is on YouTube, but that it is fairly high-effort because many of the videos are an hour long, or more. Maybe we’ll convince him to share some of his favorite videos soon in a future post!
Who are your favorites to follow on social media? Are there helpful newsletters, blogs, podcasts, or anything else that we’ve missed? Let us know in the comments.
Welcome to the inaugural post of AI Law Librarians! This blog aims to delve into the intersections of generative AI, law librarianship, legal research, legal technology, legal education, teaching legal research, and perhaps other TBD topics.
The origin story of this blog is a tale as old as time – good intentions smacked up against reality and inertia. Excited about our new chatty chatbot friends that began proliferating at the end of 2022, all of us (Sarah and Sean individually, and Jenny, Becka, and Rebecca collectively) thought to ourselves, “Self (“selves” in the case of the trio), I/we should start a blog about generative AI from the law librarian perspective! The initial enthusiasm was real – we each jumped on creating sites or/and snapping up domain names. However, we each soon realized it would be a lot of work, and our initial efforts never really took flight, in fact, the fledgling fell out of the nest into a caldera of molten lava – until now!
Sarah
My own little slice of the story is that, after several years as a RIPS Law Librarian Blog contributor, I was suddenly out of things to say, so I resigned in 2021. However, when ChatGPT-3.5 hit the scene at the end of 2022, I was so taken with the new technology that I started to have, like…thoughts again and began to barrage the editor with unsolicited ChatGPT guest posts.
Finally, after years of anticipation harking back to the days of The Flintstones, my robot companion had finally arrived—or at least a version of it. And as the excitement/apprehension in the media grew, it became evident that interest in generative AI was going to survive beyond the usual hype cycle. This new technology wasn’t merely a chatbot for amusement, it was poised to remake (erm… or destroy) the world as we know it and revolutionize everything, including law practice and education. Suspecting that the RIPS Law Librarian Blog editor was tiring of my unsolicited musings, I considered starting my own blog and even went as far as creating a WordPress site, only to quickly abandon the idea after deciding it would be too much work.
I will leave Sean his own slice of the origin story, but we had previously discussed the lack of outlets for law librarian blog posts about ChatGPT et al. After reading a particularly informative guest blog post by him on the RIPS-SIS blog entitled The Case for LLM Optimism, I emailed to throw out the idea of starting our own blog. To my mild surprise, he readily agreed (sun devils and wildcats unite!), and we searched our minds for a domain name and some like-minded folks to join us on this unprofitable adventure, and shortly thereafter, AI Law Librarians was born.
Sean
In my journey to the blog, I recently penned a couple of articles I posted on SSRN about fine-tuning LLMs for legal practice and the innovative use of chatbots by law students, and a couple of blog posts which had no obvious home in law library publications. Like Sarah, I didn’t want to swamp the RIPS-SIS blog editor with guest posts, and I had the idea of starting my old blog. As I was planning to escape the Arizona desert for a new job as the Director of Technology Innovation in Oklahoma, Sarah emailed me and suggested we start our own blog, and I was like, “Let’s get on Zoom today!” The brainstorming for domain names was brief—Sarah had a few ideas, and then “ailawlibrarians.com” popped into our minds. We pondered who to ask to join our endeavor for a few days before deciding on Rebecca, who had seemed interested in AI at the LIT-SIS roundtable in Boston.
Rebecca
I have been scrambling since November 2022 to understand this new technology and how it will affect legal research and writing. Several months ago, I connected with Jenny and Becka, and we have presented several times over the summer (together and separately) on AI and the law, mostly to faculty and attorneys. Then Sarah and Sean approached me just as the summer was coming to a conclusion and I realized that despite wanted to write on these topics these summer, I hadn’t actually *published* anything. I had a few blog posts in the hopper, so it was perfect timing. I shared with them that a couple of librarian colleagues, Jenny and Becka, and I had begun our own blog venture with the name chatgptandfriends.com, which was currently stalled after a “Hello World” WordPress post. But then, an idea emerged – why don’t the five of us combine efforts? Sarah and Sean were excited by the prospect of getting three people by asking just one, and Jenny and Becka agreed.
Becka
I had taught AI and the Law twice when generative AI became something that everyone knew and was worried about. The more I read about generative AI, the more concerned I became – not because I was worried about academic misconduct or cheating, but because I was worried that law faculty and law librarians would swing the teaching pendulum so far back in the other direction that it would harm some of our most vulnerable students. There were legal issues, ethics issues, pedagogy issues, and places where AI intersected with the other courses I teach: Education Law and Disability Law. Jenny and I talked about how to get the word about the learning positive and negative uses of AI out there and then Jenny brought in Rebecca. The three of us have been talking for months and I’ve also been talking with my university’s committee on generative AI and the law school’s. When Rebecca heard from Sarah, it made sense for all of us to get together.
Jenny
As Becka noted, I like generative AI. My origin story is not nearly as exciting as some…”I teach law practice technology, so I better check this thing out…well, this is going to cause a fuss when people don’t realize it hallucinates!”