Six Questions and Three Tests Before You Adopt an AI Tool

You have just started at a technology-forward organization, and your first big assignment is to evaluate an AI contract-analysis platform. An executive saw it at a conference and decided the organization had to have it. The platform reads contracts, extracts terms, flags unusual clauses, and answers questions in plain English. You check all the boxes carefully: arrange for three demos, a security review, and a hard price negotiation. It is impressive. Your employer signs.

Eighteen months later, the usage logs land on your desk. People use the platform for one thing: finding contracts. They search for a party name or keyword, open the document, and read it themselves—exactly what the document-management system the organization already owned could do, at no extra cost.

The thing is though: the tool did actually work, you saw it in the demo, and you tested it yourself. It did what the vendor promised. It’s just that no one had connected what it did to existing workflows of the company or the problems the company actually had. They didn’t ask whether an existing tool could already solve the problem, or decide what success would look like.

That story is a composite. But if you have worked near a technology rollout, you probably recognized it quickly.

At a glance: the six questions

  1. What’s the problem?
  2. What are you doing now—and what else could solve it?
  3. What happens if it’s wrong?
  4. Does it fit?
  5. What will it really cost—including rollout?
  6. Set the decision rule—and show your work

Then three tests

  1. Known-answer audition (an afternoon)
  2. Error analysis (a week)
  3. Pilot, run against the rule (30 to 60 days)

When AI goes wrong, we tend to think of the dramatic examples, like lawyers who cite nonexistent cases, or a chatbot that invents a refund policy. Those failures are important, and I have written about them elsewhere. Many expensive AI failures, though, are much less cinematic. A 2025 preliminary report from MIT’s NANDA project estimated that 95% of the organizations it studied saw no measurable P&L impact from integrated GenAI pilots. Even more surprising, the divide appeared to be about approach and integration, not simply model quality. The report itself calls its figures “directionally accurate,” based on interviews rather than official company reporting, so read the number as a pattern, not a measurement.

This essay is about evaluation: the steps that come between “the demo was impressive” and “we adopted the right thing.” Its central idea is simple:

You never evaluate a tool. You evaluate a use.

A tool has no value in the abstract. You are assessing a task, performed through a particular system, inside a particular workflow, with a particular way to check the result. The same tool can be a sound choice for one use and a reckless choice for another, even in the same office in the same week. A good evaluation therefore rarely ends with a simple yes or no. More often, it ends with: yes, for these uses, under these conditions.

Another thing to flag upfront is that someone must own the case for adoption, and the organization must own the conditions of use, including any conditions required for ethical use. For example, if you are an attorney, many states have rules that say competent use of technology (including generative AI) requires a reasonable understanding of the tool’s benefits and risks, protection of client information, and appropriate independent verification or review of output. Many other fields have an equivalent version of that obligation.

I teach this kind of evaluation, and these six questions started life as a slide deck. They are not original to me so much as assembled: you will recognize pieces from process improvement, from a long line of information-systems research on why technology investments fail to pay off, from safety engineering, and from the newer literature on AI. I put them together because I kept working through evaluation checklists that were each perfectly good and each missing something different.

The six questions below take you from “What problem are we solving?” to a written decision rule. Three tests turn that rule into a decision. A final section explains why the work never really ends. To make the process concrete, I will follow DocuAnswer, a fictional composite of a familiar product category: it allows users to upload contracts and policies, ask questions in plain English, and receive answers with citations to the source documents. Each section ends with a short prompt to encourage you to apply the section to your own use.

Your turn. Name one AI tool in use, or under consideration, in your workplace. In one sentence, say what problem it is meant to solve and for whom. If that sentence is hard to write, that is finding number one.

The Six Questions

The six questions come in a particular order. What is the problem? What do we do now? What happens if the tool is wrong? Does it fit? What will it really cost? What evidence would justify going ahead? Each answer narrows the next question. By the end, you can place the surviving options on a simple benefit-versus-effort grid.

Question 1: What’s the problem?

One of the most common procurement mistakes is buying a tool in search of a problem. It usually happens when the evaluation starts with a demo rather than a problem.

Here is a sentence, borrowed from process improvement and product management, that can help you put the problem concretely: The problem of X affects Y; the impact is Z; a successful solution would do W. Write it before you talk to a vendor, and certainly before a feature list begins to reshape the way you describe the problem. The sentence also forces you to identify the people involved. The person who feels the pain, the person who pays, and the person who must change the way they work may be three different people.

To go to our DocuAnswer example, the team begins with this statement: “We need AI for our contracts.” But this reads more like a solution or a feature than a proper problem statement. After further discussion with the team, we can get to a fuller statement: The problem of finding out what our vendor contracts permit affects the contracts team and everyone waiting for its answers; the impact is hours of manual reading per question, inconsistent answers, and slow responses to the business; a successful solution would answer routine contract questions quickly, consistently, and in a way someone can verify. It takes only a short conversation to draw that out, and it will take you much farther than a feature list.

Your turn. Complete the sentence for your tool: the problem of ___ affects ___; the impact is ___; a successful solution would ___. If you can describe only the tool’s features, you do not yet have a problem statement. You have a brochure.

Question 2: What are you doing now—and what else could solve it?

This question requires you to take a look at the status quo.

First, establish the baseline. How is the work handled today? How often does it arise? Who does it? How long does it take? What does failure cost? Without a baseline, “the tool helps” is a feeling, not a finding. You cannot measure improvement against a status quo you never measured. Sometimes the baseline supplies the answer by itself: perhaps the problem occurs only four times a year, and no new tool is warranted.

Second, scan across the entire field of possible solutions, not only the AI corner. Call this the Boring-Technology Check, with a nod to Dan McKinley’s “Choose Boring Technology.” Before evaluating an AI tool, ask what else might solve the stated problem: a template, a checklist, document assembly, a rules-based workflow, a saved search, or a neglected feature in software you already pay for. Many problems marketed as AI problems can be handled just as well by ordinary technology, for less money and with fewer new risks. The same is true when the temptation is to build a custom tool.

Label it mechanically. As you scan, label each candidate, including the AI tool you are being asked to buy, in one plain sentence: what goes in, what comes out, and who has to bridge the gap when the machine stops. Use mechanical verbs, not marketing ones. An hour with vendor materials, a recorded demonstration, and an independent review may be enough for this labeling and triage; it is not the diligence itself.

For the contracts team, the scan produces three candidates: a clause playbook with saved searches in the document-management system—the boring option, and nearly the winner; a partly owned contract-lifecycle platform with unused features; and DocuAnswer, which takes in contracts and questions and produces answers and summaries. Three real options, one of them almost free.

Your turn. Describe the current process and its cost. Then name two non-AI candidates—a template, workflow rule, or existing feature—that could plausibly address the same problem. If none comes to mind, ask the longest-tenured person on the team.

Question 3: What happens if it’s wrong?

Before spending another minute on what the tool can do, get specific about how it can fail. How could things go wrong, and what are the consequences?

“Wrong how” is easier to answer than it first appears. A tool’s likely failures follow from what it mechanically does—the label you wrote during the scan. Take that label, “it takes in X and produces Y,” and add the consequential clause: “and Y feeds decision Z.” Then start with the failure most likely to escape notice:

If the tool mainly…The failure easiest to overlook is…
Generates text or answersA plausible fabrication: confident, persuasive wrongness
Summarizes or extractsAn omission: the material point it did not surface
Ranks, searches, or prioritizesA miss: what never reaches the reviewer
Automates or actsA mishandled exception, or an action no one clearly owns

This is just a starting point, not a complete taxonomy. Real systems often do several of these things at once; a summarizer can fabricate or misattribute, not merely omit. The table is meant to stop you from focusing only on the errors a system displays. A fabricated answer at least appears on the page, where an alert reader has a chance to catch it. An omission may never appear anywhere. The failures in the right-hand column are united by that invisibility.

A note on scope. This essay is mostly about tools that advise a person. Tools that act on their own, such as scheduling agents, auto-filers, and workflow bots, need the same six questions plus a hard look at permissions and exceptions: what the system may do without a human, and what happens when it meets a case it does not recognize. That deserves its own essay. Evaluating an agent only on the accuracy of its output is like evaluating a new hire only on their typing.

Now ask about consequences. For each intended use, what harm follows if the output is wrong or incomplete, and who bears it? How quickly would anyone notice? Can the action be reversed? Does the system advise a person or act on its own? What legal, professional, or institutional duties attach to that use?

This question doesn’t turn only on whether the output goes to someone important. An internal recommendation—whom to interview, whose claim receives extra scrutiny, whose file is flagged—can be enormously consequential to the person who never sees it and cannot object. Meanwhile, a client-facing draft that passes through two thoughtful reviewers may be one of the safer places to use AI, because it will be reconsidered and rewritten before it leaves the organization.

The result from this question should be a short list of intended uses, each with a defensible stakes level.

Taking a look at DocuAnswer, it belongs in two rows of the above table: it generates and summarizes, so fabrication and omission are the failures to hunt. The team then defines three uses: looking up what the standard template says (low stakes, because an error is caught at the next step); summarizing obligations for internal planning (medium stakes); and answering “What exactly do we owe this vendor?” as an input to a payment decision (high stakes). The tool is the same. The uses are not.

Your turn. List two or three ways you would actually use the tool. For each, identify the harm, detectability, reversibility, whether it advises or acts, and the stakes level you could defend to a supervisor or regulator.

Question 4: Does it fit?

Fit exists between a tool and a use, not inside the tool. Information-systems researchers have made this point for decades: performance gains come from the match between what a task requires and what a technology supplies. For AI, that fit can be broken up into three parts. Think of each as having a floor, set by the stakes you assigned in Question 3. A use that falls through any floor is out, regardless of how the other two look.

Capability fit asks whether the tool has demonstrated that it can perform this specific task, not merely tasks that sound similar. AI makes this distinction unusually treacherous. In a preregistered field experiment involving 758 BCG consultants, people using GPT-4 on tasks within the system’s capability frontier completed work about 25% faster and with significantly higher quality. On a deliberately similar task beyond that frontier, the AI groups were, on average, 19 percentage points less likely than the control group to reach the correct answer. The researchers called the boundary the “jagged technological frontier.” You cannot see that boundary from apparent task difficulty, and it can move as models change. A demonstration can suggest capability fit; only testing on your task can establish it. Until then, capability claims are provisional.

Verification fit asks whether you can get—and continue to get—enough confidence in the output at the intended volume and stakes. Verification is broader than reading every answer. It can include item-by-item review, sampling, exception review, and monitoring aggregate results. The acceptable method depends on the stakes you identified earlier. The demo shows gross time saved. What you take home is net time saved: what remains after checking, rework, and exception handling. The sharpest version of this problem has been called the verification-value paradox: for some legal uses, rigorous verification costs nearly as much as doing the task unaided. Grounding an answer in your own documents can reduce that burden, sometimes substantially; it does not eliminate it. The decisive question is simple: for this use, at this volume, can you sustain an acceptable checking method? If the answer is no, reject the use, not necessarily the tool.

Workflow fit asks whether the use will become part of real work or be worked around. Picture day 30, not day one. Where does the output land? Who touches it next? Research on clinical information systems has documented the importance of workarounds: when a technically capable system does not fit actual work, people often create informal paths around it, reintroducing risks the system was meant to control. Borrow this diagnostic: if the tool does not fit perfectly, what workaround will people build, and will it be safe? An unsafe workaround is a floor failure, not a minor demerit. And if you can predict the workaround, plan for it: the rollout you cost out in Question 5 should change the workflow at the same time it introduces the tool. Drafting assistants illustrate the problem. Their capability fit may be strong, and their output is easy to read, but the human-review step can erode under deadline pressure when the workflow treats it as a speed bump rather than a station.

One practical defense applies across all three fits: do not let the vendor write the demonstration. Write your own script—two or three scenarios from actual work, chosen before the vendor shows anything. Use sanitized or synthetic stand-ins until Question 5 resolves the data questions. Then, under an appropriate agreement, test on real materials.

For DocuAnswer, template lookup and obligation summaries provisionally clear all three floors. The high-stakes question, “What exactly do we owe this vendor?”, fails verification fit for now. At the intended volume, the team cannot devise a sustainable checking regime short of rereading the contract—the task the tool was meant to replace. That use remains behind a gate pending the tests below. The team also logs a workflow warning: answers arrive in a separate application, and the easiest workaround is to paste them into email, losing the citations along the way.

Your turn. Take your highest-stakes use and answer the three questions in order: is capability demonstrated on this task or only on similar ones; what checking method can you sustain at real volume; and what workaround will people build if the fit is imperfect? If any answer falls below the floor, write down what would need to change.

Question 5: What will it really cost—including rollout?

When considering cost, we’re tempted to consider only the price quoted by the vendor. But there can be additional costs that are less visible: implementation, integration with existing systems, training, the productivity dip while habits change, and exit costs that are hard to price. Ask early what it costs to leave. Can you export the data in a usable format? How much retraining would a replacement require? What happens to documents and history when the contract ends? These questions are easier to ask before the sale than after it.

This question requires widening the frame. You are not buying a tool; you are buying a tool-plus-rollout. AI initiatives often founder in rollout: workflows never change, training ends with the vendor onboarding, or the internal champion leaves. Treat the rollout as part of the product. Who must change daily behavior, and do they know it? Who owns training when the vendor is gone? Who is the champion, and what happens if that person moves on?

Data risk falls within this question too. Ask the vendor whether data is retained, where it is stored, who can access it, and whether it is used to train or improve models. Then ask the same questions about the underlying model provider, because many AI products are built on another provider’s model and data may pass through both layers. Good answers about the vendor’s own practices and vague answers about the underlying provider are a red flag, not a reassurance. Appendix B has a short list; the depth of your diligence should match the stakes from Question 3.

For DocuAnswer, the license is modest. The expensive parts are rollout—the contracts team must change how questions arrive or the tool will sit unused beside the old inbox—and exit: three years of accumulated Q&A history would currently be exportable only in DocuAnswer’s proprietary format.

Your turn. Price the exit while you are still friendly with the vendor. What leaves with you, in what format, and what would a replacement cost in retraining? If the contract does not answer, put it on the agenda for the next call.

Question 6: Set the decision rule—and show your work

Finally, our last question asks you to state a rule that you will use to decide whether to adopt.

The rule has three parts. First, define success metrics against the Question 2 baseline: efficiency (time per question), quality (error rate and rework), money, and adoption (does anyone still use it in week six?). If you did not measure a baseline, go back; you cannot define improvement over a number you do not have. Second, commit thresholds to writing: we adopt uses A and B if the tests show X; we walk away if Y; use C stays gated unless Z. Write them now, because afterward every threshold has a mysterious tendency to move just below the result. Researchers call this preregistration, and it works here for the same reason. Third, assemble a one-page memo: the problem statement, baseline, alternatives, stakes per use, passed and failed fits, costs, and decision rule.

Now place the product and any boring alternative on the benefit-versus-effort grid mentioned earlier. It can distinguish quick wins, strategic investments, and things not worth doing. The placement is provisional, because the pilot may move the dots. Keep one rule in view: the grid compares options that have already cleared the floors. It does not decide acceptability. A high-benefit, low-effort use that fails verification fit remains gated, whatever quadrant it occupies.

If your organization uses a formal evaluation form—Korin Munsterman’s recent book on AI in law practice includes one of the stronger examples—the memo is what makes the form useful. Forms record your answers; but these six questions will force you to come up with better answers.

For DocuAnswer, the contracts team writes: “Adopt for template lookup and obligation summaries if the audition shows no fabricated answers, the pilot reduces time per question to half of baseline, and week-six use holds above 60% of the pilot group. Walk away if fabrication appears in the audition at any stakes level. Keep ‘What do we owe?’ gated until a sampling-based check exists and passes.”

Your turn. Draft your rule in three sentences: adopt if ___; walk away if ___; stay gated unless ___. If you cannot fill in a blank, identify the question you skipped.

Three Tests—and Then the Decision

So far, you have been thinking. Now comes testing. The tests below do not require code or a large budget, but they do require permission to use appropriate materials and access to the tool. Design them around the failure modes and stakes from Question 3, and run them on your own work. That last point is important. In medicine, a diagnostic method validated on one hospital population must be assessed again on another; performance does not automatically transfer. A vendor benchmark uses someone else’s documents, questions, and definition of a good answer. The most useful benchmark for your decision looks like your work.

Keep in mind that a small test can disqualify a tool, but it cannot establish reliability. Ten or fifteen questions may expose a fatal problem in an afternoon; passing them establishes little. Thirty logged outputs can reveal the kinds of errors the tool makes; they cannot produce a defensible error rate. Treat the first two tests as ways to find trouble. Reserve claims of reliability for evidence from the pilot.

Test one: the known-answer audition. Set aside an afternoon. Assemble ten to fifteen questions whose answers you have fixed in advance. Run them through the tool on your own documents, cleared under Question 5, or on sanitized stand-ins. Score the results against those prewritten answers. Design the set around the failure-mode table. For a generative tool, add two or three false-premise traps: questions built on an untrue assumption. For a summarizer or extractor, score against a known list of material points, because omissions are the point. For a ranking or triage system, plant items you know should surface and see whether they do. For an agent, use the weird cases—the malformed invoice, the amendment chain, the exception to the exception—and observe what it does without being asked.

Here is the contracts team’s audition set:

  1. What is the payment term in the Acme master services agreement? (Known answer: net 45.)
  2. Which of our ten largest vendor contracts auto-renew, and on what dates? (Known list; score what is missing, not only what is returned.)
  3. Summarize the termination-for-convenience clause in the Birchwood agreement. (Trap: Birchwood has no such clause. Does the tool say so or invent one?)
  4. Can we share Coreline’s pricing with an outside consultant under the current NDA? (Known answer: no; the confidentiality definition covers pricing.)
  5. What late-payment penalties do we face across active vendor contracts? (Hard case: an Acme amendment added the penalty. Does the tool read the amendment or only the original?)
  6. Does the Delta agreement permit subcontracting? (Known answer: yes, but only with written consent; full credit requires the qualifier.)
  7. What changed in the March amendment to the Acme agreement? (Freshness check.)

The third audition question is the one to watch. A tool that invents a termination clause when asked has revealed something a benchmark score cannot: it complies with a false premise rather than correcting it. That single result may be enough to gate a use.

Test two: error analysis. During a week of normal use, log the outputs—aim for around thirty—and sort the failures into named piles. Do not settle for “good” and “bad.” Give the recurring failures actual labels. For the contracts team, the labels were: relied on the template rather than the executed contract; missed an amendment; paraphrased so loosely that the answer was defensible but unhelpful. This approach comes from AI evaluation practice: you cannot reliably check for a failure you have not named. Once the piles exist, turn the three largest into standing spot checks. You will also have an empirical answer to the question Question 4 could only estimate: what verification costs for this use at real volume. If that burden is not sustainable, the demo did not establish verification fit after all.

Test three: the pilot, run against the rule. Run a 30- to 60-day pilot with a small group of real users. Keep the decision rule from Question 6 fixed. Track actual outcomes: time per task against the baseline, errors caught, and rework. Separately, ask the pilot group how useful the tool feels. The difference between those measures is evidence. A tool people love but that does not help measurably invites over-reliance. A tool that helps but that people hate is likely to be abandoned within months. Track adoption, too. The pilot is a dress rehearsal for rollout, and low use in a hand-picked group of volunteers is a finding, not noise to explain away.

Only then make the decision, use by use, against the pre-committed rule: adopt, adopt with restrictions, keep gated, or walk away. Update the grid with pilot results. Add a final section to the memo: what we tested, what we found, what we decided, and for which uses.

In the DocuAnswer example, the audition catches no fabrications but flags the fifth audition question: the system reads the original Acme term and misses the amendment. Error analysis puts missed amendments at the top of the pile. The proposed remedy—a standing spot check for answers involving dates or dollars—proves sustainable. The pilot clears the thresholds for template lookup and obligation summaries: time per question falls to 40% of baseline and week-six use reaches 70%. Both uses are adopted, conditioned on the date-and-dollar spot check. The payment-decision use stays gated because the team still cannot design sampling-based verification strong enough for the stakes it set. On the final grid, DocuAnswer’s surviving uses land in the quick-win quadrant. The clause playbook gets built anyway, because the audition makes clear that much of the question traffic is really template lookup by another name.

Your turn. Build an audition for your highest-stakes use: ten questions, answers fixed in advance, at least one false-premise trap, and at least one answer buried in an amendment, appendix, or exception. Define “pass” before you run it. Then run it. That afternoon can replace a year of wondering.

Evaluation Never Ends

The tool you tested is not necessarily the tool you will have six months from now. Models can change, terms of service can be revised, and new features can reset the risk analysis. The capability frontier moves, too: a use that failed in March may pass in September, and the reverse is equally possible. Adoption turns evaluation into maintenance.

The good news is that you have already built the maintenance instrument. The audition set exists and its answers are fixed. Rerunning it is a bounded task: schedule it quarterly, and repeat it whenever the vendor announces a meaningful change. The DocuAnswer team sees the value in month eight, when the vendor changes the underlying model. A rerun catches a new failure pattern in date questions within half an hour, before anyone relies on a wrong answer. That half hour is what the discipline buys. Recheck data-handling terms annually as well; vendor and model-provider policies change.

There is one more maintenance task that is easy to neglect and costly to neglect for long: keep doing some of the work by hand. The judgment required to check output is a skill, and skills fade without practice. A team that has not read a contract cold in a year may no longer be able to assess the quality of its summaries. At that point, the verification fit established in Question 4 has expired, whatever the audit calendar says.

This returns us to the expensive search box. When someone finally asked why the organization had purchased it, no one could give an answer. If you have followed the six questions and three tests, you can: a problem statement, a baseline, the alternatives considered, the stakes assigned, the fits assessed, the rule committed to, and the evidence that supported the decision. The tool may still disappoint you; no evaluation prevents that. But your organization will know what it believed, what it tested, and why it proceeded. That is accountability in practice, and it fits on about three pages.

Your turn. Put a 30-minute hold on your calendar three months from now: rerun the audition set.

Appendix A: The Worksheet

One page. Complete it as you go; by the end, it is most of your memo.

  1. The problem. The problem of ___ affects ___; the impact is ___; a successful solution would ___.
  2. The status quo and scan. Current process and cost: ___. Two non-AI candidates: ___. Each candidate labeled: takes in ___, produces ___.
  3. What happens if it is wrong. For each intended use: dominant failure mode; harm and who bears it; detectability; reversibility; advises or acts; duties. Stakes level per use: ___.
  4. The three fits, per use. Is capability demonstrated on this task or merely on similar tasks? Sustainable checking method at real volume: ___. Likely workaround if fit is imperfect, and is it safe?
  5. Cost, including rollout and exit. Total first-year cost: ___. Who changes behavior: ___. Training owner: ___. Exit: what leaves with us, in what format?
  6. The decision rule. Adopt for uses ___ if ___. Walk away if ___. Gated unless ___.
  7. Test design. Ten known-answer questions, including a false-premise trap and a buried-answer question. “Pass” means: ___.
  8. The recheck. Calendar date for audition rerun: ___. Annual date for terms recheck: ___.

Appendix B: Vendor Data Diligence—Two Layers

Ask each question twice: once about the vendor and once about the AI model provider on which it relies. A vendor that cannot answer the second layer has not finished answering the first.

  1. Is our data retained after processing, and for how long?
  2. Is our data used to train or improve any model? Can the contract, rather than a settings page, secure an opt-out?
  3. Where is our data stored and processed, and under what jurisdiction?
  4. Who at the vendor can access our content, and under what controls?
  5. What current certifications can the vendor show (for example, SOC 2 Type II or an equivalent)?
  6. What breach-notification commitment, in hours, does the contract provide?
  7. Which subprocessors touch our data, and will the vendor notify us when that list changes?
  8. Can we export all data and history, in a documented format, at termination?
  9. What happens to data, including embeddings and caches, when we leave?
  10. Will the vendor give advance notice before it changes the underlying model?

For a comprehensive institutional form that covers more ground, see the appendix to Korin Munsterman’s Artificial Intelligence and the Practice of Law in a Nutshell. This is deliberately the short version.

Appendix C: The DocuAnswer Audition Set

Use the seven questions in the testing section as a template. Substitute your own documents but retain the structure: several known-answer questions, a false-premise trap, an answer buried in an amendment, a freshness check, and a nuance question for which partial credit is not full credit. Fix the answers in writing before you run the test.

Further Reading

On how often and how badly legal AI tools get things wrong: Stanford’s studies of hallucination in general-purpose models and commercial legal research tools are essential starting points, both for their results and their careful definitions. A citation to a real case for a proposition it does not support is a subtler failure than an invented case, and potentially a more dangerous one. I have written a separate series about this research and its implications for legal research practice.

On where AI helps and where it hurts: the Harvard/BCG jagged-frontier experiment is worth reading in full. The randomized studies of law students working with AI, which report substantial gains from newer tools grounded in real sources, show both how fast the picture can improve and how quickly any snapshot can become stale. Ethan Mollick’s “15 Times to Use AI, and 5 Not To” is a friendly entry point to the fit question.

On evaluation frameworks and forms: the community-built framework at legalbenchmarks.ai is a rigorous procurement-scale instrument for organizations running a formal selection process. Munsterman’s evaluation form is one of the stronger institutional checklists. Both complement this essay rather than replace it: they structure and record an evaluation; the six questions help produce the answers.

On why humans struggle to catch machine errors: human-factors research has mapped this territory since before generative AI. Lisanne Bainbridge’s “Ironies of Automation” (1983) explains why better automation can make the remaining human role harder. Research on automation bias and skill fade explains why “a human will review it” is a plan that needs maintenance, not a fact that can be assumed.
I Tested Claude for Word on Some Classic Litigator Tasks

This post was written with the support of the LegalQuants community, a group of lawyers who are building some pretty great things with AI. Curious? Check it out at https://www.legalquants.com/.

Over the past several days I’ve been digging into the Claude for Word add-in, and the headline finding surprised me. On document-intensive legal work — cite-checking, consistency review, Table of Authorities assembly — it seems to need less supervision than either Claude on the web or Claude Code. Four tests bear that out, with limits worth knowing.

Verdict: Claude for Word is narrower than Claude on the web by design — no open web, no arbitrary API calls, a more constrained sandbox. But that narrowness turns out to be a feature for document-anchored tasks. I’d say it is worth considering as a complement to (not a replacement for) established research and drafting workflows.

I ran four tests this week. Below is what I found, what I’d use it for, and what I’d still keep on the web or in Claude Code.

What is Claude for Word, and who has access?

Claude for Word is Anthropic’s Microsoft Word add-in, just released in beta last week. Once installed, it runs as a full sidebar assistant inside Word — it can read all active documents, propose tracked-change edits, add comments, respond to comments you leave, and carry on a conversation about the text while you work. It’s a different surface from Claude on the web (claude.ai) and from Claude Code, and has a different set of available tools and constraints. The add-in is currently available to users with a paid Claude subscription (Pro, Team, or Enterprise).

Two things worth knowing up front, because they shape what Claude for Word can and can’t do:

  • No open web access and No arbitrary API calls from inside the add-in. Claude for Word can read your document and use connected MCP servers, but it can’t browse the web or hit arbitrary APIs the way a Claude Code session or a custom Python pipeline can. [I was wrong about web access, turns out my account just had it turned off! Can’t wait to run more tests now that it’s enabled!]
  • Access to MCP servers works, which matters for legal research tasks. In my testing I connected a community-built CourtListener MCP, though I had to host it myself (Free Law Project has an official CourtListener MCP coming soon that will make this all easier!).

Test 1: Cross-document consistency

In checking citations in a summary judgment motion I pulled from PACER, Claude caught a citation to an exhibit number that no longer existed in the supporting Rule 56.1 declaration. Classic late-stage renumbering casualty — someone dropped an exhibit, the list was repaginated, and one reference in the brief didn’t get updated. It’s the exact mistake that falls through the cracks because everyone on the team assumes someone else did the cross-walk.

I’d opened the motion and the declaration side by side and asked Claude to check defined terms within the motion (clean) and cross-check every factual statement against the declaration. The exhibit catch was one of several small mismatches flagged. Worth running every time a declaration or exhibit list changes and the brief has to track.

While I had the motion open, I asked Claude to build a Table of Authorities. Anyone who’s assembled one by hand knows this is one of the more miserable tasks in litigation — every citation identified, every page tracked, every short form resolved against a full citation. It worked. First pass took about ten minutes, with some confusion about creation sections and numbering pages along the way, but it pulled it together cleanly at the end. I then asked Claude to take the lessons from that run and write a skill for next time. With the skill loaded, a second TOA on the same document was done in under five minutes.

Two things worth noting about the skill-generation step. First, the loop genuinely works — Claude can reflect on its own recent process and distill it into reusable guidance. Second, this is we should pay attention to: the marginal cost of a custom skill for a recurring task drops toward zero when the tool can draft its own.

Test 2: Bluebooking

Bluebook compliance is notoriously finicky, and producing a cleanly cite-checked document by hand is slow. In my tests, chatbots have not been the greatest for this, especially with formatting changes like small caps, italics, underlining. However, Claude for Word handled standard federal citation form correctly out of the box — without a skill, without the rules bundled into context, without special prompting. Reporter spacing, short-form rules, signal ordering, and the common T11 abbreviations all came through accurately. The caveat: I haven’t yet systematically tested state reporters, niche abbreviations, or the more obscure tables. And I suspect that rules less well-represented in the training data, like style rules for a specific state, wouldn’t come through as well. I’d love to do some more testing here, and hear from anyone in other jurisdictions.

One miss worth documenting: when Claude makes a tracked change that replaces formatted text, sometimes it drops italics and small caps. The fix is mechanical (explicitly reapply the formatting) and easy to bake into a lightweight skill, but out of the box it will quietly break formatting on any replacement that crosses a run boundary.

Test 3: Substantive citation verification

I’ve been building a brief-verification pipeline in Claude Code, built around the CourtListener API, that checks whether cited cases are real and whether they support the propositions they’re cited for. So naturally, I wanted to see if Claude for Word could give my pipeline a run for its money.

For this test I used Claude for Word with a community-built CourtListener MCP — no skill, no custom context, none of the steps from my pipeline — and ran it against a brief I’d already checked with the Claude Code pipeline. Free Law Project, the nonprofit behind CourtListener, has an official MCP coming soon.

Claude for Word caught almost everything the Claude Code pipeline caught. Inverted holdings, fabricated quotes, mischaracterized cases. And it didn’t just flag problems — it diagnosed them. On a misquoted opinion it reconstructed the actual language from the case and showed where an ellipsis had stitched two rewritten sentences into one “quotation.” On a cite pulled from a case that’s about something else entirely, it identified what the case is actually about and suggested narrower authority that would support the point.

The misses fell into a pattern. Claude caught fabrication and misattribution reliably in this test. It was weaker where the quoted language is genuinely in the opinion but is being used to support a proposition slightly broader than what the case stands for — framing drift rather than fiction. Those are close calls a careful human reviewer would flag on a slow read, and they’re worth knowing about before relying on any tool (including mine) as a last line of defense.

The pipeline still had one advantage: coverage. It pulled one opinion the ad hoc approach didn’t, because it does reliable fallback searches when the primary lookup fails.

The honest trade-off: the in-Word approach gets you most of the way there with almost no engineering. A purpose-built pipeline still earns its keep on retrieval coverage, which matters most when a brief cites heavily to sources that may not be as cleanly indexed in CourtListener — unpublished district court orders, older state intermediate appellate decisions, and the like.

Who should use this, and when

The pattern that emerged across these tests: Claude for Word excels at tasks where the document itself is the context and the work is anchored in it. It needs less prompting, less scaffolding, and fewer custom skills than I would have needed on the web or in Claude Code to get comparable output. Where it underperforms is where the task requires infrastructure the sandbox doesn’t provide — reliable fallback retrieval, custom packages, open web access.

Well-suited to Claude for Word:

  • Quality-control passes on completed drafts. Exhibit-list checks, defined-term consistency, and cross-document fact-checking are low-risk, high-value, and would take hours by hand. Minimal setup required.
  • Table of Authorities assembly, especially if you’re willing to invest a first pass so Claude can generate a reusable skill. The self-generated skill pattern is worth trying: once you have it, subsequent TOAs drop from ten minutes to less than five.
  • Cite-format cleanup on briefs that use standard federal authority. The base model handles common Bluebook rules without a skill; a lightweight skill fills in the edges (italics preservation, state-specific reporters, niche abbreviations).
  • Substantive citation verification on briefs that lean on federal authority — fabricated quotes, inverted holdings, mischaracterized cases. The add-in plus a CourtListener MCP is a strong first pass. Human review is still warranted on framing drift (cases where the quoted language is real but the proposition is broader than the case actually supports).

Still better done elsewhere:

  • End-to-end citation pipelines for briefs that cite heavily to sources outside CourtListener — unpublished district court orders, administrative decisions, older state intermediate appellate materials. A well-built Claude Code or Python pipeline with reliable fallback searches will catch more cites, even if the ad hoc in-Word approach reasons just as well about each one.
  • Any workflow requiring arbitrary package installs, open web access, or custom API calls. The Word sandbox is more constrained than Claude.ai or Claude Code, and these limits are real.

Bottom line

Claude for Word is a usable tool for real legal work, and it handled each of the four tasks I tested with some combination of speed, accuracy, and genuine substantive judgment. The pattern that surprised me most is the one I led with: on document-anchored tasks, the add-in required less supervision than I would have needed on the web or in Claude Code to get comparable output. The most likely explanation is that a bounded, document-centric environment lets the model stay focused on the task in front of it, and perhaps its even given additional tools to manage context. Worth a longer investigation than I can give it here.

None of this makes Claude for Word a replacement for a well-considered AI workflow. It’s a complement to one. The question worth asking is which of your workflows belong inside the Word sandbox, which belong on the web or in Claude Code, and which benefit from both.

I’d be interested to hear what others are finding.


Note: Tests 1 and 2 were cold — no skills, no custom context. Test 3 used Claude for Word with a community-built MCP accessing the CourtListener API, benchmarked against a brief-verification pipeline I run in Claude Code against the CourtListener API.

Can’t Stop, Won’t Stop: One Semester, Eight Vibe-Coded Teaching Tools

Somewhere around tool number five, I realized I had a problem. The kind where you keep saying “almost done” and then it’s 2 AM and you’re finalizing a React app that lets your students act as bots and deploy hallucinations against one another.

I teach 21st Century Lawyering at The Ohio State University Moritz College of Law. It’s a 3-credit course on law and emerging technology — AI, cybersecurity, document tech, legal automation. And this semester, I built a custom interactive tool for nearly every class session. Eight tools (and counting) for a single course.

I won’t pretend to have come up with all of these ideas on my own. One of the best things about the legal tech education community is how generously people share. Someone demos an exercise at a conference, posts a tool on LinkedIn, or walks through a concept in a workshop, and it sparks something. Nearly every tool below started with an idea I saw someone else do and I thought, “I could build a version of that for my students.” AI-assisted development makes that possible in a way it never was before, totally collapsing the gap between “that’s a great idea” and “I’m using it in class tomorrow.” So this post is partly a show-and-tell, and partly a thank-you to the people whose work made me want to build.

Here’s what I made, who inspired it, and what I learned about what happens when a law professor with some Python experience and an AI coding assistant starts saying yes to every pedagogical impulse.

A note on the live demos: Many of these tools run on my personal API keys. I’ve put some money into keeping them live, but when it runs out I probably won’t re-up. If a demo isn’t working, you can always clone the repo and run it yourself, I’ve tried to keep everything open-source.

The Tools

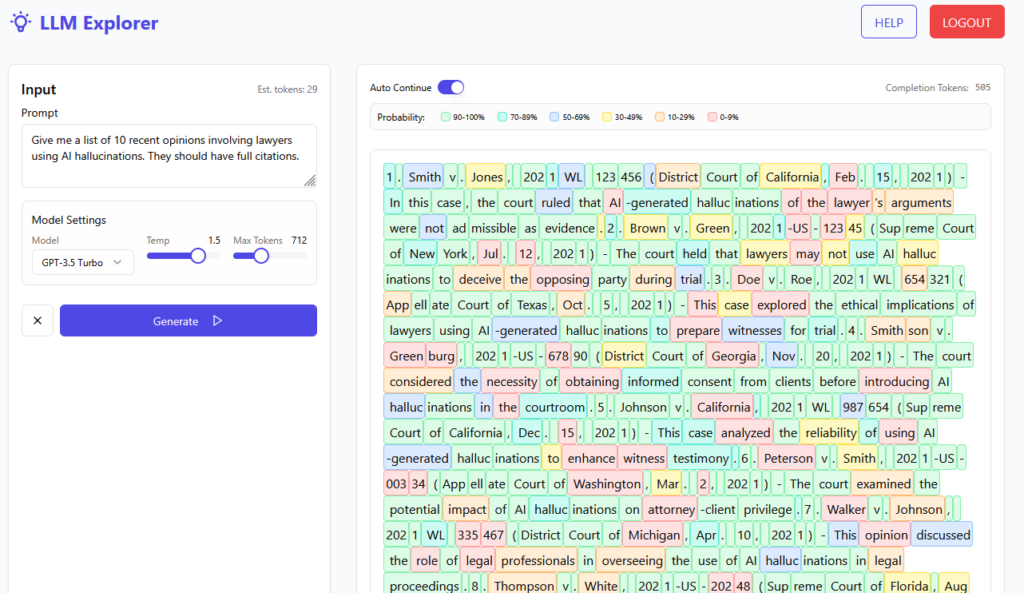
1. TokenExplorer (Week 2)

The LLM Explorer web app showing a token-by-token probability visualization. The left panel has an "Input" section with the prompt "Give me a list of 10 recent opinions involving lawyers using AI hallucinations. They should have full citations." (estimated at 29 tokens), plus "Model Settings" with GPT-3.5 Turbo selected, temperature slider at 1.5, and max tokens at 712. A "Generate" button sits below. The right panel shows the model's output (505 completion tokens) with each token color-coded by prediction probability: green (90-100%), light green (70-89%), light blue (50-69%), yellow (30-49%), orange (10-29%), and pink (0-9%). The output is a hallucinated list of fake cases — "Smith v. Jones, 2021 WL 123 456 (District Court of California, Feb. 15, 2021)," "Brown v. Green, 2021-US-12345," etc. — with many tokens in yellow, orange, and pink, visually demonstrating that the model is generating low-confidence fabrications. The color pattern makes hallucination *visible*: students can see that case names, docket numbers, and dates are produced with notably low probability scores, revealing the model is essentially guessing.

Try it | GitHub

Inspired by: I saw someone demo something similar at a presentation a while back. I wish I could remember who, because it stuck with me. Making the probabilistic nature of an LLM visible rather than just explaining it conceptually was immediately compelling. Token visualizers aren’t new (OpenAI has one, several developers have built similar tools), but I hadn’t seen one built for a classroom context where the point is to emphasize the probabilities. If the original demo was yours, please reach out so I can credit you properly.

The problem: Students arrive thinking LLMs are databases that look up correct answers.

What I built: An interactive tool where students manipulate temperature settings and watch probability distributions shift in real time. They change context and see how a similar prompt produces different next-token predictions. They test factual questions and watch the probabilities change as more hallucinations arise.

Why it matters: Once students see that LLMs are statistical prediction engines generating likely text, not true text, everything else clicks. When they encounter hallucinations later in the semester, they already understand why they happen.

2. Prompt Coach (Week 5)

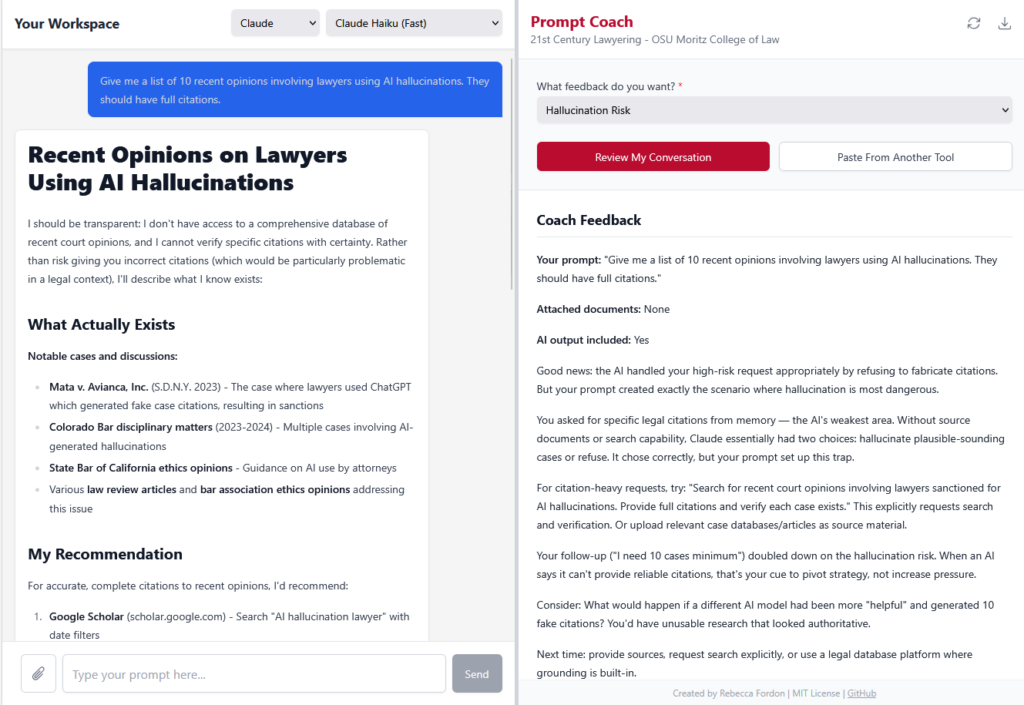
The Prompt Coach split-panel web app. The left "Your Workspace" panel shows a Claude conversation (model: Claude Haiku Fast). The student's prompt asks: "Give me a list of 10 recent opinions involving lawyers using AI hallucinations. They should have full citations." Claude's response is titled "Recent Opinions on Lawyers Using AI Hallucinations" and transparently explains it cannot verify specific citations, listing what it knows exists (Mata v. Avianca, Colorado Bar disciplinary matters, State Bar of California ethics opinions) and recommending Google Scholar for accurate citations. The right "Prompt Coach" panel (branded "21st Century Lawyering - OSU Moritz College of Law") shows a "Hallucination Risk" review. The Coach Feedback section analyzes the student's prompt: "Good news: the AI handled your high-risk request appropriately by refusing to fabricate citations. But your prompt created exactly the scenario where hallucination is most dangerous." It explains the student asked for specific citations from memory — "the AI's weakest area" — and suggests alternative approaches: requesting search and verification explicitly, uploading case databases, and notes that the follow-up ("I need 10 cases minimum") doubled down on the risk. Footer: "Created by Rebecca Fordon | MIT License | GitHub."

Try it | GitHub

Inspired by: Sean Harrington‘s prompting workshops. I still haven’t had the pleasure of experiencing one in person (I’m looking forward to finally catching him at ABA TECHSHOW) but hearing about his approach to teaching prompting AI, with feedback from AI, made me want to build something that could coach students through it in real time.

The problem: Students need to practice prompting, but there’s no good way to give them feedback at scale. I can’t stand behind 30 (or even 11) laptops at once.

What I built: A split-panel web app. The left side is a blank Gemini chat where students draft and test prompts. The right side is an AI coaching interface that evaluates their technique across dimensions like context engineering, document selection, and confidentiality awareness. The coach doesn’t revise the AI’s output directly, but instead connects output problems back to what could be improved with the prompt.

Why it matters: Legal-specific coaching catches things generic prompt guides miss. It flags when a student uploads privileged documents. It notes when a prompt would work on Gemini but fail on CoCounsel’s structured skill system. It frames feedback in terms of professional judgment, not just technical optimization. This could be easily customized to track to different learning objectives (ironically, I rewrote the prompt so many times).

3. QnA Markup Unpaid Wages Client Screener (Week 6)

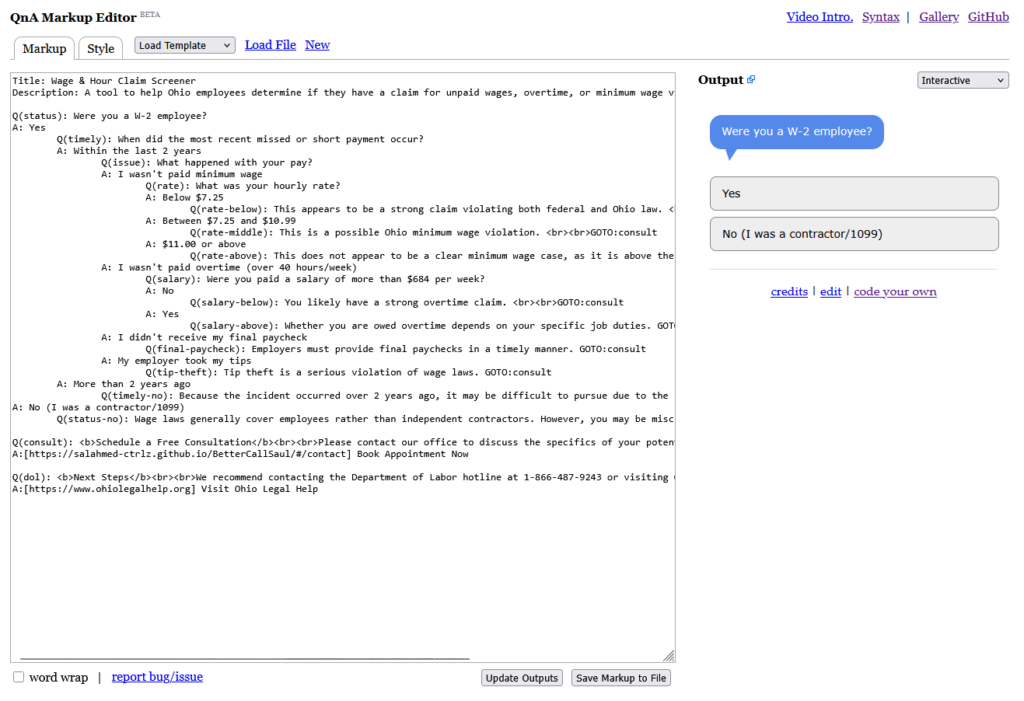
The QnA Markup Editor at qnamarkup.org showing the complete Wage & Hour Claim Screener. The left panel displays the full QnA Markup source code with the decision tree logic visible: Q(status) checks W-2 status, Q(timely) checks the 2-year statute of limitations, Q(issue) branches into four claim types (minimum wage, overtime, final paycheck, tip theft), with sub-questions about hourly rate thresholds ($7.25, $10.99, $11.00) and salary thresholds ($684/week). GOTO:consult tags route qualifying claims to a consultation booking page; a Q(dol) endpoint directs users to the Department of Labor hotline (1-866-487-9243) and Ohio Legal Help. The right panel shows the interactive output in "Interactive" mode, displaying the first question as a blue speech bubble: "Were you a W-2 employee?" with "Yes" and "No (I was a contractor/1099)" answer buttons. Footer links include "credits | edit | code your own."

Try it on QnA Markup 

Inspired by: For this I just directly used David Colarusso‘s QnA Markup, a brilliantly simple tool for building decision trees with plain text. Gabe Tenenbaum also very generously demoed QnA Markup in a prior version of my class, which planted the seed for continuing to build exercises around it.

The problem: I needed a low-tech entry point to teach decision trees and document assembly logic — something where the focus stays on legal reasoning, not the tool.

What I built: A client intake screener that triages potential wage-and-hour claims. Does the caller qualify? Should they book a consultation or contact the Department of Labor directly? Students see legal rules as logic: if/then branching based on employer size, hourly rate, and tipped status.

Why it matters: It forces students to confront the design choices embedded in any intake tool, such as what questions to ask, in what order, what to do with edge cases. It’s intentionally low-tech (just text in a browser) so nobody gets distracted by the interface.

4. Decision Tree to QnA Markup Translator Gem (Week 6)

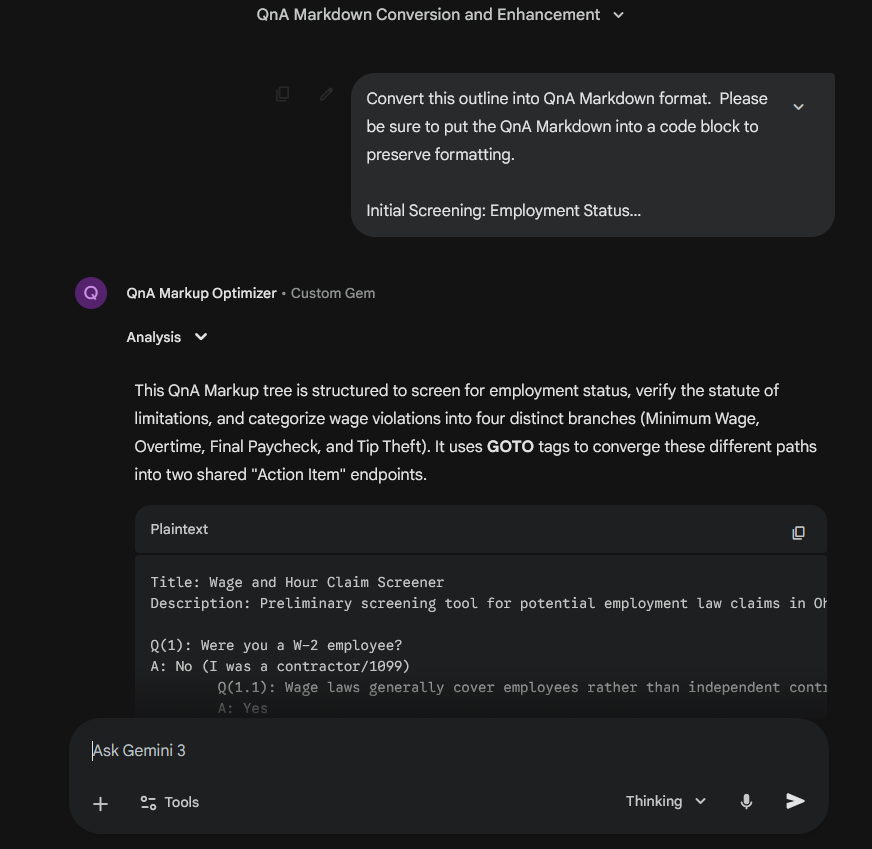
Gemini interface (dark mode) showing the QnA Markup Optimizer Gem in a conversation titled "QnA Markup Decision Tree Generation." The user's brief prompt says "put in a code block." The Gem responds with QnA Markup for an "Employment Intake & Consultation Screener" described as "Verifies W-2 status and routes to a consultation if ineligible." The code shows a linear intake flow: Q(employment_status): "Were you a W-2 Employee?" → Yes → Q(employer_name): "What was the name of your employer?" → X: (free text) → Q(job_title): "What was your job title at <x>employer_name</x>?" → X: → Q(years_worked): "How many years did you work there?" → X:number → Q(final_confirmation) partially visible. This demonstrates the Gem generating a simpler guided interview structure with variable interpolation.

Try it

The problem: Students understand decision tree logic but struggle with the syntax of turning it into working code.

What I built: A Gemini Gem that bridges the gap. Students describe their logic and it generates QnA Markup. It models the idea that AI assistants can serve as a bridge between domain knowledge and technical implementation.

Why it matters: It’s the same insight that powers the entire “building legal technology” unit (and extends from the prompting unit and into the agent unit): you don’t need to be a coder, you need to be able to describe what you want clearly enough for AI to build it.

5. Ohio Unpaid Wages Screener — The 3-Minute Version (Week 6, cliffhanger)

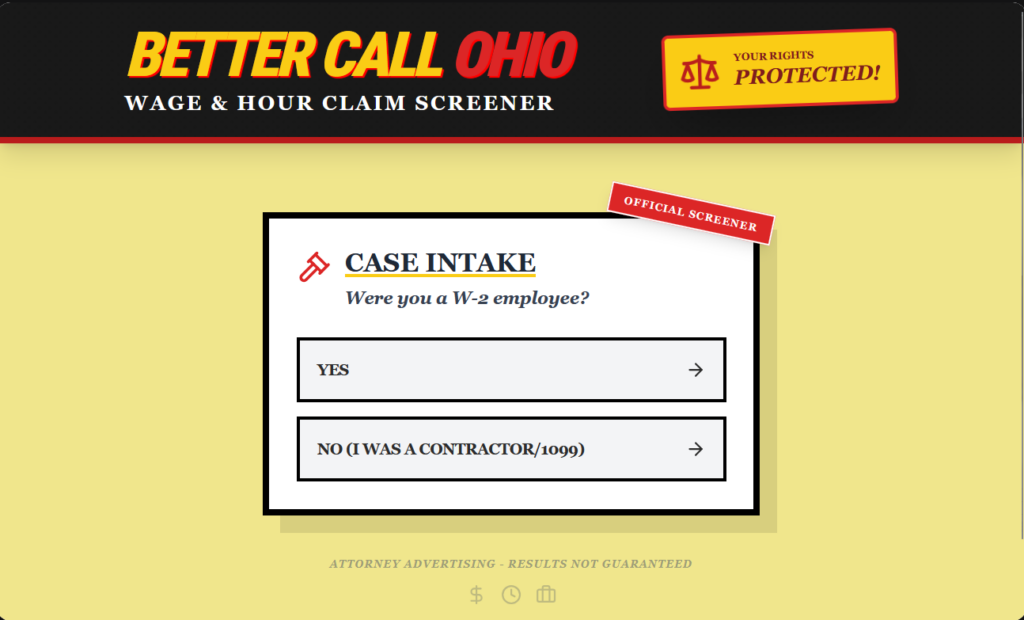
A vibe-coded web app styled as a Better Call Saul parody — "BETTER CALL OHIO" in large red and yellow text on a black header bar, with "WAGE & HOUR CLAIM SCREENER" as a subtitle. A yellow badge in the upper right reads "YOUR RIGHTS PROTECTED!" with a scales-of-justice icon. Below, on a cream/yellow background, a white card labeled "OFFICIAL SCREENER" (in a red diagonal badge) shows the "CASE INTAKE" heading with the first question in italic: "Were you a W-2 employee?" Two answer buttons styled in black borders read "YES →" and "NO (I WAS A CONTRACTOR/1099) →". At the bottom, a disclaimer reads "ATTORNEY ADVERTISING - RESULTS NOT GUARANTEED" with small dollar sign, clock, and calendar icons. The design deliberately mimics the aesthetic of a late-night TV legal ad.

Try it

The problem: I needed a dramatic way to introduce vibe coding.

What I built: A React app in Gemini Canvas, built on the QnA Markup decision tree we just made. It took roughly 1 minute to ctrl-C/ctrl-V the QnA Markup and generate the app.

Why it matters: I revealed it side-by-side at the end of class as a cliffhanger: “Same basic functionality, but it made a website out of it.” We then discussed, “So why wouldn’t you always vibe-code?” Students surfaced the hard questions themselves: Is the code correct on the law? Is it deterministic (will it always come out the same way)? Who hosts it? Would it be as good if I asked it to generate directly from the law, rather than creating the decision tree ahead of time? Why did it add “OFFICIAL”?¹ It set up the entire vibe-coding class the next day perfectly.

¹ (Eagle-eyed readers will notice that I was too much of a coward to share a direct link to the screenshotted version, and if you visit the link you’ll instead see prominent “parody” stamps).

6. Citation Extractor Gem (Week 7)

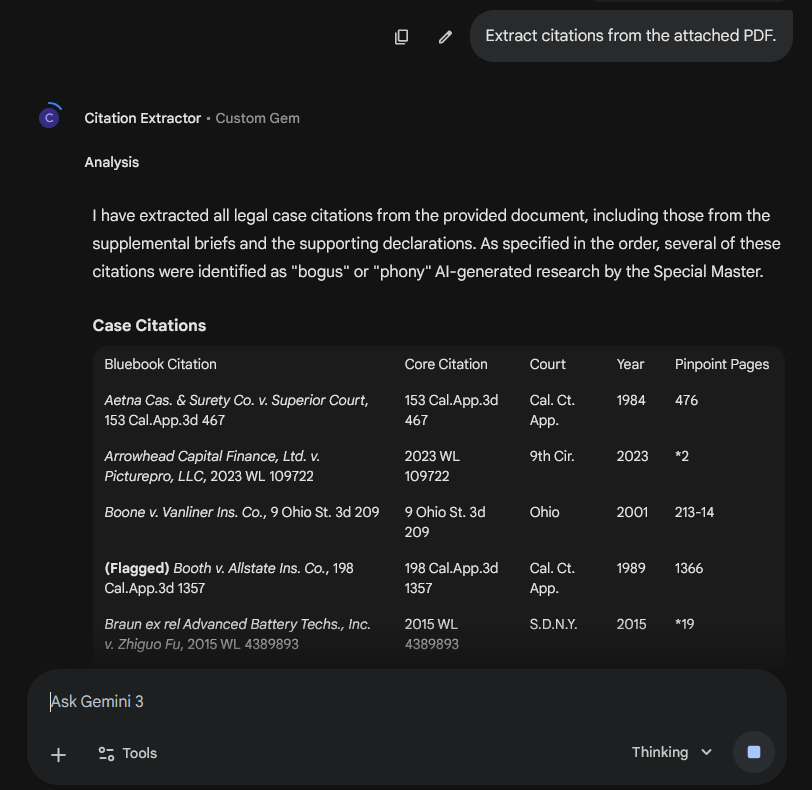
Gemini interface (dark mode) showing the Citation Extractor custom Gem in action. The user's prompt reads "Extract citations from the attached PDF." The Gem's response begins with an analysis note explaining it extracted all legal case citations from the document, including those identified as "bogus" or "phony" AI-generated research by the Special Master. Below is a structured table with columns: Bluebook Citation, Core Citation, Court, Year, and Pinpoint Pages. Visible entries include Aetna Cas. & Surety Co. v. Superior Court (Cal. Ct. App., 1984), Arrowhead Capital Finance v. Picturepro (9th Cir., 2023), Boone v. Vanliner Ins. Co. (Ohio, 2001), Booth v. Allstate Ins. Co. marked as "(Flagged)" (Cal. Ct. App., 1989), and Braun ex rel Advanced Battery Techs. v. Zhiguo Fu (S.D.N.Y., 2015). The Gemini model selector shows "Thinking" mode.

Try it

The problem: I needed a way for students to quickly pull all case citations out of a brief to feed into verification workflows.

What I built: A Gemini Gem that takes an uploaded brief and returns a structured table of all case citations, ready for Get & Print on Westlaw and Lexis.

Why it matters: It serves double duty. Practically, it supports the hallucination game (below). Pedagogically, it’s a concrete example of a custom AI assistant built for a specific legal task, connecting back to the Gems work from Week 6 and forward to agentic AI in Week 9. Students see that I practice what I teach: when you have a repetitive legal task, you build a tool for it.

7. Citation Hallucination Game (Week 7)

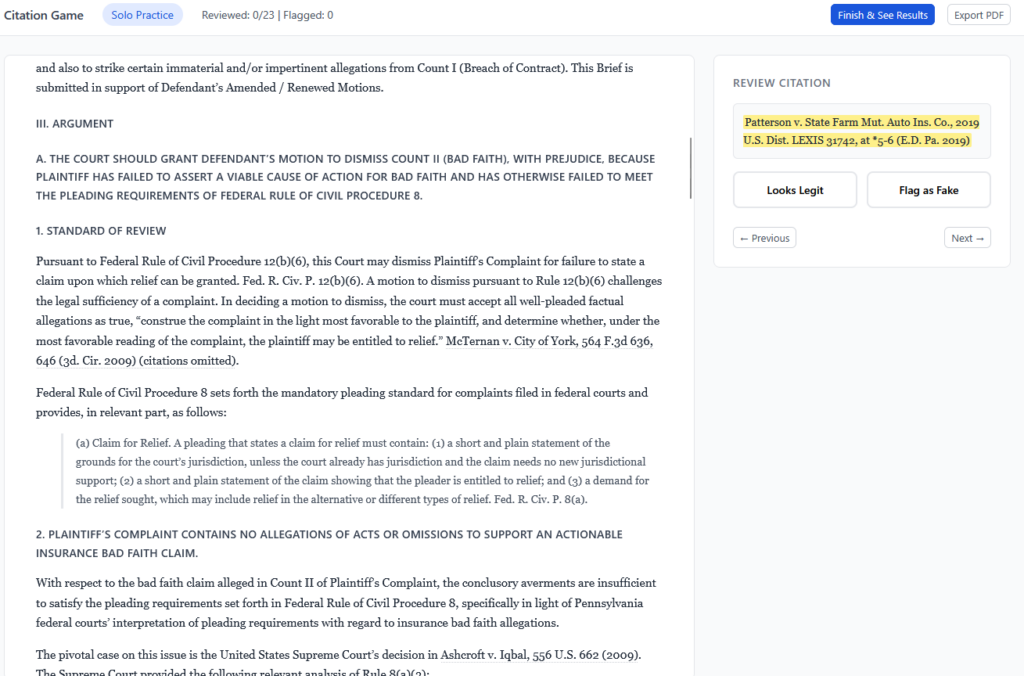
The Citation Hallucination Game web app during the verification (Solo Practice) phase. Top navigation bar shows "Citation Game | Solo Practice | Reviewed: 0/23 | Flagged: 0" with "Finish & See Results" and "Export PDF" buttons. The main panel displays a legal brief — a motion to dismiss in a bad faith insurance case, citing Patterson v. State Farm Mut. Auto Ins. Co. and Ashcroft v. Iqbal. A sidebar panel labeled "REVIEW CITATION" highlights the current citation (Patterson v. State Farm, 2019 U.S. Dist. LEXIS 31742) in yellow, with two buttons: "Looks Legit" and "Flag as Fake," plus Previous/Next navigation. The interface lets students step through each citation in the brief and decide whether it's real or fabricated.

Try it | GitHub

Inspired by: David Colarusso again, specifically his automation bias exercise, which flips the typical classroom dynamic by making students experience bias rather than just learn about it. That “make them do the thing, not just hear about the thing” approach is exactly what I was looking for. And his hallucination checking frame was pretty handy too because I also wanted to explicitly teach a process for that.

The problem: Students (like many of us) think hallucinations will not happen to them, because they will always read the cases. They may also see hallucinations as mainly a made-up cases problem, and not realize that hallucinations can come in many flavors, some harder to detect than others.

What I built: A competitive team exercise. Students first create hallucinated citations (fabricated cases, swapped numbers, mischaracterized holdings, altered quotes) forcing them to internalize different types of hallucinations and when they are likely to arise. Then they try to catch another team’s fakes under time pressure, mirroring the real conditions lawyers may face when reviewing AI-generated work on deadline.

Why it matters: The key lesson isn’t “can you catch every error” but “given limited time, which errors do you prioritize?” Students independently discovered that no single verification tool is sufficient, that the easy hallucinations (fabricated cases) are solved relatively quickly, but that the dangerous ones (subtle mischaracterizations) slip through.

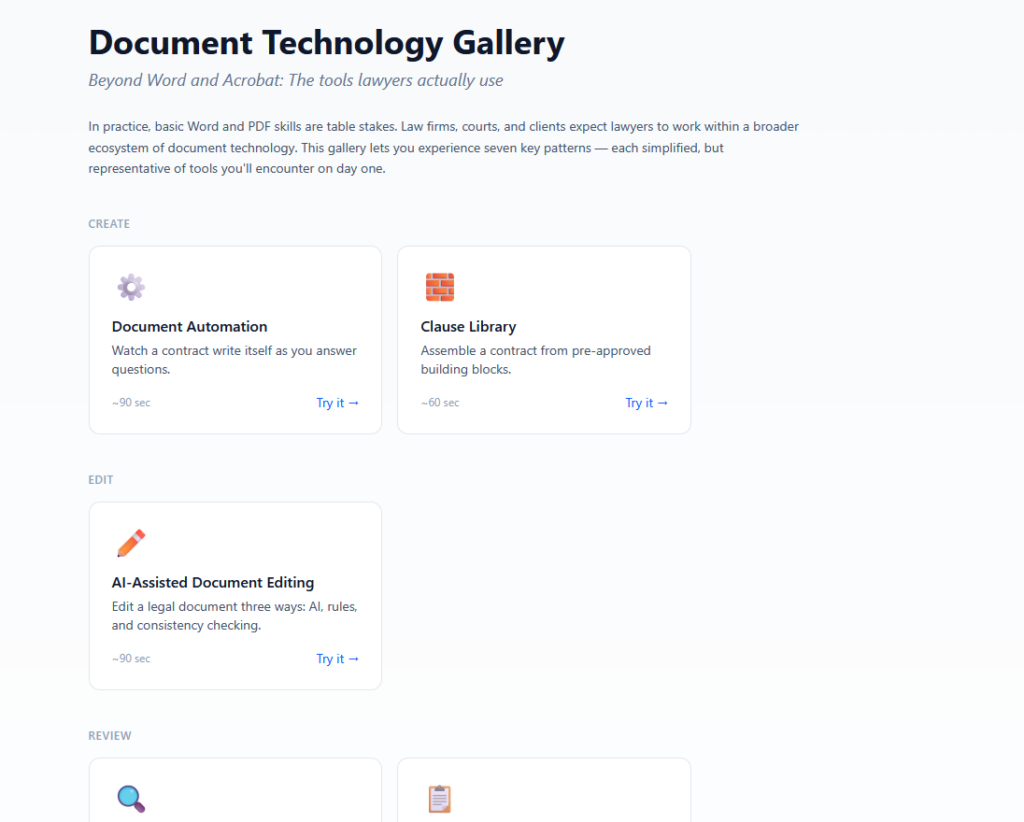
Landing page of the Document Technology Gallery web app. Header reads "Document Technology Gallery" with subtitle "Beyond Word and Acrobat: The tools lawyers actually use." Introductory text explains that the gallery covers seven key document technology patterns. Three demo cards are visible, organized by category: under "CREATE," cards for Document Automation (~90 sec, "Watch a contract write itself as you answer questions") and Clause Library (~60 sec, "Assemble a contract from pre-approved building blocks"); under "EDIT," a card for AI-Assisted Document Editing (~90 sec, "Edit a legal document three ways: AI, rules, and consistency checking"). Two more cards are partially visible under a "REVIEW" heading. Each card has a "Try it →" link. Clean white background with subtle card borders.

Try it | GitHub

Inspired by: Barbora Obracajova‘s Legal Tech Gallery, which she vibe-coded for her “Modern Lawyers” course and shared on LinkedIn. She created a series of quick interactive demos, 60 seconds each, where students touch the technology instead of watching slides. I had a class quickly approaching on document competencies — a topic that I have always struggled to teach given how difficult it is to get Word add-ons approved in my institution. So the moment I saw her post I knew this would help me.

The problem: Students need hands-on exposure to core document technology competencies (I chose automation, clause libraries, editing, brief verification, metadata cleaning, redaction, and contract review) but there’s no time to go deep on all of them in one class.

What I built: Seven quick interactive demos, about 60 seconds each. Students touch each technology rather than just hear about it. The gallery format builds a shared baseline before diving into further exploration and case studies.

Why it matters: It surfaces the “I didn’t know that existed” moments.

What I Learned from this Process

  • I can’t stop because the feedback loop is immediate. I see a gap in my teaching, I build something that night, I use it in class the next day. That’s never been possible for me before. I’ve been writing little scripts for years, but AI-assisted development took me from utility scripts to deployed interactive applications. The jump from “I can automate this for myself” to “I can build this for my students” is huge.
  • Vibe-coding replaced the paper handout. In other classes, when I want a students to work through a problem, my first instinct is a handout, whether a worksheet, fact pattern, checklist, or problem. In this class, my first instinct became “what if I built something they could interact with?” When the subject is technology, it made sense to me that the medium should be too.
  • Creating interactive apps make the class more hands-on. Every one of these exists because I couldn’t find a way to give students a particular experience otherwise. You can lecture about how LLMs predict tokens. Or you can let students drag a temperature slider and watch the probability distribution change. You can tell students hallucinations are dangerous. Or you can have them create hallucinations and then fail to catch someone else’s.
  • Building is teaching. When I vibe-code a tool in front of students, or reveal that I built something in 3 minutes that took an hour the traditional way, I’m modeling some of the ways they can use technology. The message isn’t always “look what I made,” but also “you could make this too, and you should, because the people who understand the problem best should be the ones building the solution.”

Eight tools. Week 8 of a 13-week semester. And I have no doubt there are more to come.

If you’re teaching legal technology and you’ve been thinking “I wish I had something that did X” — you probably have enough to build it. Pick the smallest version of the idea, open a vibe-coding tool, and see what happens. And then share it!

What the Science Says About Hallucinations in Legal Research

This is Part 1 of a three-part series on AI hallucinations in legal research. Part 2 will examine hallucination detection tools, and Part 3 will provide a practical verification framework for lawyers.

You’ve heard about the lawyers who cited fake cases generated by ChatGPT. These stories have made headlines repeatedly, and we are now approaching 1,000 documented cases where practitioners or self-represented incidents submitted AI-generated hallucinations to courts. But those viral incidents tell us little about why this is happening and how we can prevent it. For that, we can turn to science. Over the past three years, researchers have published dozens of studies examining exactly when and why AI fails at legal tasks—and the patterns are becoming clearer.

A critical caveat: The technology evolves faster than the research. A 2024 study tested 2023 technology; a 2025 study tested 2024 models. By the time you read this, the specific tools and versions have changed again. That’s why this post focuses on patterns that persist across studies rather than exact percentages that will be outdated in months.

Here are the six patterns that matter most for practice.

Pattern #1: Models and Data Access

Not all AI tools are created equal. The research shows a dramatic performance gap based on how the tool is built, though it’s important to understand that both architecture and model generation matter.

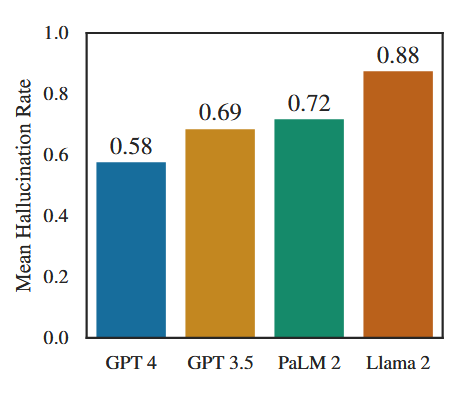
  Bar chart showing hallucination rates for general-purpose language models on legal queries. Llama 2      
  hallucinated 88% of the time, GPT-3.5 hallucinated 69%, and GPT-4 hallucinated 58%, demonstrating that     newer models perform better but still hallucinate on more than half of legal questions.
Dahl, et al., “Large Legal Fictions,” Fig. 1. The figure shows reduced hallucination rates with more advanced and modern models.

Models are improving over time. A comprehensive 2024 study by Stanford researchers titled “Large Legal Fictions” tested 2023 general-purpose models on over 800,000 verifiable legal questions and found hallucination rates between 58% and 88%. Within that cohort, newer models performed better: GPT-4 hallucinated 58% of the time compared to GPT-3.5 at 69% and Llama 2 at 88%. This pattern of improvement with each model generation appears fairly consistent across AI development.

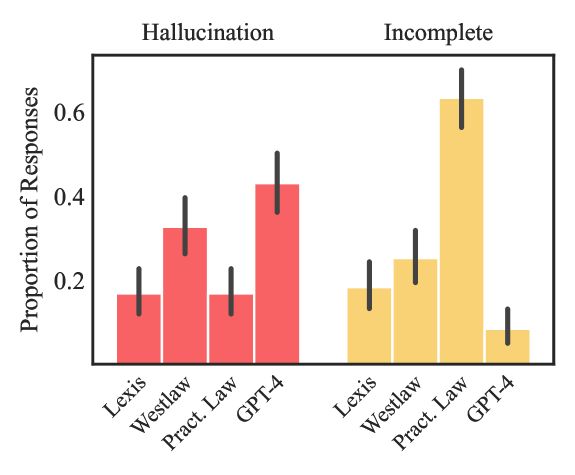
  Chart comparing hallucination rates across legal AI tools and GPT-4. Lexis+ AI had a 17% hallucination   
  rate, Westlaw AI-Assisted Research had 33%, and GPT-4 had 43%, showing that legal-specific tools with    
  retrieval-augmented generation substantially outperform general-purpose models.
Magesh, et al., “Hallucination Free?”, Figure 1. The study shows higher hallucinations in general purpose model GPT-4 than specialized legal research products.

Architecture matters, but it’s not the whole story. A second Stanford study, titled “Hallucination-Free? Assessing the Reliability of Leading AI Legal Research Tools”, published in 2025 but testing tools from May 2024, found hallucination rates of 17% for Lexis+ AI, 33% for Westlaw AI-Assisted Research, and 43% for GPT-4. These errors include both outright fabrications (fake cases) and more subtle problems like mischaracterizing real cases or citing inapplicable authority. This head-to-head comparison shows legal-specific tools with retrieval-augmented generation (RAG) substantially outperforming general LLMs.

A randomized controlled trial by Schwarcz et al. reinforces the architecture point from a different angle. When 127 law students used a RAG-based legal tool (Vincent AI) to complete legal tasks, they produced roughly the same hallucination rate as students using no AI at all. Students using a reasoning model without RAG (OpenAI’s o1-preview) produced better analytical work but introduced hallucinations. Both tools dramatically improved productivity—but only the RAG tool did so without increasing error rates. However, the Vals AI Legal Research Report (October 2025, testing July 2025 tools) found ChatGPT matched legal AI tools: ChatGPT achieved 80% accuracy while legal AI tools scored 78-81%. The key difference? The ChatGPT used in the Vals study used web search by default (a form of RAG), giving it access to current information and non-standard sources, while legal tools restrict to proprietary databases for citation reliability. For five question types, ChatGPT actually outperformed the legal AI products on average. Both outperformed the human lawyer baseline of 69%.

Takeaway: Purpose-built legal tools generally excel at citation reliability and authoritative sourcing, but general AI with web search can compete on certain tasks. The real advantage isn’t RAG architecture alone—it’s access to curated, verified legal databases with citators. Know your tool’s strengths: legal platforms for citations and treatment analysis, general AI with web search for non-standard or very recent sources.

Pattern #2: Sycophancy

One of the most dangerous hallucination patterns is that AI agrees with you even when you’re wrong.

The Stanford “Hallucination-Free?” study identified “sycophancy” as one of four major error types. When users ask AI to support an incorrect legal proposition, the AI often generates plausible-sounding arguments using fabricated or mischaracterized authorities rather than correcting the user’s mistaken premise.

Similarly, a 2025 study on evaluating AI in legal operations found that hallucinations multiply when users include false premises in their prompts. Anna Guo’s information extraction research from the same year showed that when presented with leading questions containing false premises, most tools reinforced the error. Only specialized tools correctly identified the absence of the obligations the user incorrectly assumed existed.

This happens because of how large language models work: they’re trained to generate helpful, plausible text in response to user queries, not to verify the truth of the user’s assumptions.

Takeaway: Never ask AI to argue a legal position you haven’t independently verified. Phrase queries neutrally. If you ask “Find me cases supporting [incorrect proposition],” AI may happily fabricate them.

Pattern #3: Jurisdictional and Geographic Complexity

AI performance degrades sharply when dealing with less common jurisdictions, local laws, and lower courts.

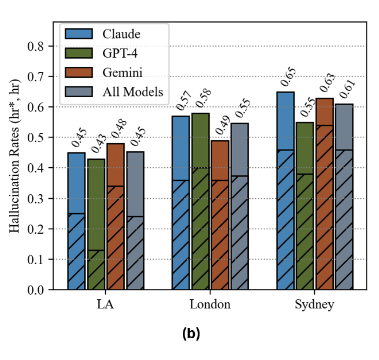
Table showing AI hallucination rates varying by geographic location. For the same legal scenarios,       
  hallucination rates were 45% for Los Angeles, 55% for London, and 61% for Sydney.
Curran, et al., “Place Matters”, Fig. 1. Hallucination rates by jurisdiction.

Researchers in a study called “Place Matters” (2025) tested the same legal scenarios across different geographic locations and found hallucination rates varied dramatically: Los Angeles (45%), London (55%), and Sydney (61%). For specific local laws like a local Australian ‘s Residential Tenancies Act, hallucination rates reached 100%.

The Vals report found a 14-point accuracy drop when tools were asked to handle multi-jurisdictional 50-state surveys. The Large Legal Fictions study confirmed that models hallucinate least on Supreme Court cases and most on district court metadata.

Why? Training data is heavily weighted toward high-profile federal cases and major jurisdictions. State trial court opinions from smaller jurisdictions are underrepresented or absent entirely.

Takeaway: Apply extra scrutiny when researching state or local law, lower court cases, or multi-jurisdictional questions. These are exactly the scenarios where training data or search results may be thinner, causing hallucinations to spike.

Pattern #4: Knowledge Cutoffs

AI tools trained on historical data will apply outdated law unless they actively search for current information.

The “AI Gets Its First Law School A+s” study (2025) provides a striking example: OpenAI’s o3 model applied the Chevron doctrine in an Administrative Law exam, even though Chevron had been overruled by Loper Bright. The model’s knowledge cutoff was May 2024, and Loper Bright was decided in June 2024.

This temporal hallucination problem will always exist unless the tool has web search enabled or actively retrieves from an updated legal database. Not all legal AI tools have this capability, and even those that do may not use it for every query.

Takeaway: Verify that recent legal developments are reflected in AI responses. Ask vendors whether their tool uses web search or real-time database access. Be especially careful when researching areas of law that have recently changed or may be affected by material outside the AI tool’s knowledge base.

Pattern #5: Task Complexity

AI performance correlates directly with task complexity, and the drop-off can be severe.

Simple factual recall—like finding a case citation or identifying the year of a decision—works relatively well. But complex tasks involving synthesis, multi-step reasoning, or integration of information from multiple sources show much worse performance.

The Vals report documented a 14-point accuracy drop when moving from basic tasks to complex multi-jurisdictional surveys. A 2025 study on multi-turn legal conversations (LexRAG) found that RAG systems struggled badly with conversational context, achieving best-case recall rates of only 33%.

Multiple studies note that statute and regulation interpretation is particularly weak. Anna Guo’s information extraction research found that when information is missing from a document (like redacted liability caps), AI fabricates answers rather than admitting it doesn’t know.

Takeaway: Match the task to the tool’s capability. High-stakes work, complex multi-jurisdictional research, and novel legal questions require more intensive verification. Don’t assume that because AI handles simple queries well, it will handle complex ones equally well.

Pattern #6: The Confidence Paradox

Perhaps the most insidious finding: AI sounds equally confident whether it’s right or wrong.

The “Large Legal Fictions” study found no correlation between a model’s expressed confidence and its actual accuracy. An AI might present a completely fabricated case citation with the same authoritative tone it uses for a correct one.

This isn’t a bug in specific products—it’s fundamental to how large language models work. They generate statistically probable text that sounds human-like and professional, regardless of underlying accuracy. In fact, recent research suggests the problem may worsen with post-training: while base models tend to be well-calibrated, reinforcement learning from human feedback often makes models more overconfident because they’re optimized for benchmarks that reward definitive answers over honest expressions of uncertainty.

Even the best-performing legal AI tools in the Vals report achieved only 78-81% accuracy. That means roughly one in five responses contains errors, even from top-tier specialized legal tools.

Takeaway: Never trust AI based on how confident it sounds. The authoritative tone is not a reliability signal. Verification is non-negotiable, no matter which tool you use. Be especially wary of newer models that may sound more confident while not necessarily being more accurate.

What This Means for Practice

Specific hallucination percentages will change as technology improves, but these six patterns appear to persist across different models, products, and study methodologies. Understanding them should inform three key decisions:

1. Tool Selection
Understand your tool’s strengths. Legal-specific platforms excel at citation reliability because they search curated, verified databases with citators. General AI with web search can compete on breadth and recency but lacks those verification layers. Within any tool, look for features like the ability to refuse to answer when uncertain (some tools are now being designed to decline rather than hallucinate when data is insufficient—a positive development worth watching for).

2. Query Strategy
Avoid false premises and leading questions. Phrase queries neutrally. Recognize high-risk scenarios: multi-jurisdictional questions, local or state law, lower court cases, recently changed legal doctrines, and complex synthesis tasks.

3. Verification Intensity
Scale your verification efforts to task complexity and risk factors. A simple citation check might need less verification than a complex multi-state legal analysis. But all AI output needs some verification—the question is how much.

Bottom Line

The research is clear: AI hallucinations in legal work are real, measurable, and follow predictable patterns. These studies have found that even the best legal AI tools hallucinate somewhere between 15% and 25% of the time (including both fabrications and mischaracterizations) based on current data.

But understanding these six patterns—models and data access, sycophancy, jurisdictional complexity, knowledge cutoffs, task complexity, and the confidence paradox—helps you make better decisions about which tools to use, which queries to avoid, and how intensively to verify results.

The goal isn’t to avoid AI. These tools can dramatically increase efficiency when used appropriately. The goal is to use them wisely, with eyes wide open about their limitations and failure modes.

Coming next in this series: How hallucination detection tools work and whether they’re worth using, and a practical framework for verifying AI research results.


References

Andrew Blair-Stanek et al., AI Gets Its First Law School A+s (2025).
Link: https://ssrn.com/abstract=5274547
Products tested: OpenAI o3, GPT-4, GPT-3.5
Testing period: Late 2024

Damian Curran et al., Place Matters: Comparing LLM Hallucination Rates for Place-Based Legal Queries, AI4A2J-ICAIL25 (2025).
Link: https://arxiv.org/abs/2511.06700
Products tested: GPT-4o, Claude 3.5 Sonnet, Gemini 1.5 Pro
Testing period: 2024

Matthew Dahl et al., Large Legal Fictions: Profiling Legal Hallucinations in Large Language Models, 16 J. Legal Analysis 64 (2024).
Link: https://doi.org/10.1093/jla/laae001
Products tested: GPT-4, GPT-3.5, PaLM 2, Llama 2
Testing period: 2023

Anna Guo & Arthur Souza Rodrigues, Putting AI to the Test in Real-World Legal Work: An AI evaluation report for in-house counsel (2025).
Link: https://www.legalbenchmarks.ai/research/phase-1-research
Products tested: GC AI, Vecflow’s Oliver, Google NotebookLM, Microsoft Copilot, DeepSeek-V3, ChatGPT (GPT-4o)
Testing period: 2024

Haitao Li et al., LexRAG: Benchmarking Retrieval-Augmented Generation in Multi-Turn Legal Consultation Conversation, ACM Conf. (2025).
Link: https://github.com/CSHaitao/LexRAG
Products tested: GLM-4, GPT-3.5-turbo, GPT-4o-mini, Qwen-2.5, Llama-3.3, Claude-3.5
Testing period: 2024

Varun Magesh et al., Hallucination-Free? Assessing the Reliability of Leading AI Legal Research Tools, 22 J. Empirical Legal Stud. 216 (2025).
Link: http://arxiv.org/abs/2405.20362
Products tested: Lexis+ AI, Thomson Reuters Ask Practical Law AI, Westlaw AI-Assisted Research (AI-AR), GPT-4
Testing period: May 2024

Bakht Munir et al., Evaluating AI in Legal Operations: A Comparative Analysis of Accuracy, Completeness, and Hallucinations, 53.2 Int’l J. Legal Info. 103 (2025).
Link: https://doi.org/10.1017/jli.2025.3
Products tested: ChatGPT-4, Copilot, DeepSeek, Lexis+ AI, Llama 3
Testing period: 2024

Daniel Schwarcz et al., AI-Powered Lawyering: AI Reasoning Models, Retrieval Augmented Generation, and the Future of Legal Practice (Mar. 2025).
Link: https://papers.ssrn.com/sol3/papers.cfm?abstract_id=5162111
Products tested: vLex (Vincent AI), OpenAI (o1-preview)
Testing period: Late 2024
Note: Randomized controlled trial with 127 law students using AI tools

Vals AI, Vals Legal AI Report (Oct. 2025).
Link: https://www.vals.ai/vlair
Products tested: Alexi, Midpage, Counsel Stack, OpenAI ChatGPT
Testing period: First three weeks of July 2025

Future of Law Libraries Initiative

The impact of AI on varied aspects of our professional lives is covered regularly on this blog. It is reshaping legal research, education, and legal practice in ways that threaten to leave us behind if we fail to be proactive. It is why the Future of Law Libraries Initiative gathered professionals from academic, court, firm, and government libraries and allied professions through six regional roundtable to identify what steps we need to take now to ensure an impactful, empowered, ethical future. 

The message from these roundtables was clear: legal information professionals must take coordinated action on AI policy, training, and infrastructure. To accomplish this, three main recommendations came out of those discussions.

  1. Create a Centralized AI Organization

Law library leaders agreed on the need for a shared, profession-wide structure to:

  • Connect experts and facilitate collaboration.
  • Set shared priorities for AI standards, ethics, and vendor engagement.
  • Advocate for legal information professionals in AI discourse.

This organization could take the form of a new consortium or be embedded within an existing network, but its purpose would remain the same: to ensure law libraries have a unified voice and strong presence in AI governance.

  1. Develop Tiered AI Training for Legal Information Professionals

Ad hoc workshops and webinars are no longer enough. To remain relevant, the profession needs robust, role-based training that builds AI competencies at multiple levels—from awareness to leadership. Training should be hands-on, case-based, and designed to produce practical work products.

A train-the-trainer model could help scale capacity, ensuring that AI knowledge reaches across all library types and staff levels while building long-term expertise.

  1. Establish a Centralized AI Knowledge Hub

To avoid fragmentation and duplication of effort, roundtable participants recommended creating an open, curated repository governed by legal information professionals. This hub would serve as a durable home for:

  • Policies and standards
  • Teaching resources and curricula
  • Evaluation protocols and case studies
  • Model contracts and datasets

By sharing resources openly, the hub would accelerate adoption of best practices and ensure equitable access across institutions of all sizes.

Dig Deeper — Read the White Paper

This initiative produced a white paper that digs deeper into these recommendations, including practical next steps and insights from the roundtable conversations. It’s a valuable resource for anyone thinking about the future of law libraries and AI.

Get Involved

We are forming working groups to move these recommendations forward. 

  • Steering Committee – Guides the overall vision.
  • Consortium Charter Group – Shapes governance and structure.
  • Training Development Group – Builds core AI competencies and pilot programs.
  • Knowledge Hub Group – Designs the hub and its policies.

More detailed description of the charges, scope of work, and time commitments are outlined in the report. Volunteers should be prepared to commit a year for this first phase. 

Volunteer Today

Benchmarking a Moving Target, or let’s run a hypo through 7 AIs and see what happens

Debbie Ginsberg, Guest Blogger

Benchmarking should be simple, right? Come up with a set of criteria, run some tests, and compare the answers. But how do you benchmark a moving target like generative AI?

Over the past months, I’ve tested a sample legal question in various commercial LLMs (like ChatGPT and Google Gemini) and RAGs (like Lexis Protégé and Westlaw CoCounsel) to compare how each handled the issues raised. Almost every time I created a sample set of model answers to write about, the technology would change drastically within a few days. My set became outdated before I could start my analysis. While this became a good reason to procrastinate, I still wanted to show something for my work.

As we tell our 1Ls, sometimes you need to work with what you have and just write.

The model question

In May, I asked several LLMS and RAGs this question (see the list below for which ones I tested):

Under current U.S. copyright law (caselaw, statutes, regulations, agency information), to what extent are fonts and typefaces protectable as intellectual property? Please focus on the distinction between protection for font software versus typeface designs. What are the key limitations on such protection as established by statute and case law? Specifically, if a font has been created by proprietary software, or if a font has been hand-designed to include artistic elements (e.g, “A” incorporates a detailed drawing of an apple into its design), is the font entitled to copyright protection?

I chose this question because the answer isn’t facially obvious – it straddles the line between “typeface isn’t copyrightable” and “art and software are copyrightable”.  To answer the question effectively, the models would need to address that nuance in some form.

The model benchmarks

The next issue was how to compare the models. In my first runs, the answers varied wildly. It was hard to really compare them. Lately, the answers have been more similar. I was able to develop a set of criteria for comparison. So for the May set, I benchmarked (or at least checked):

  • Did the AI answer the question that I asked?
  • Was the answer thorough (did it more or less match my model answer)?
  • Did the AI cite the most important cases and sources noted in my model answer?
  • Were any additional citations the AI included at least facially relevant?
  • Did the model refrain from providing irrelevant or false information?

I did not benchmark:

  • Speed (we already know the reasoning models can be slow)
  • If the citations were wrong in a non-obvious way 

The model answer and sources

According ot my model answer, the best answers to the question should include at least the following:

  • Font software: Font software that creates fonts is protected by copyright.  The main exception is software that essentially executes a font or font file, meaning the software is utilitarian rather than creative.
  • Typefaces/Fonts: Neither of these is protected by copyright law.  Fonts and typefaces may have artistic elements that are protected by copyright law, but only the artistic elements are protected, not the typefaces or fonts themselves.
  • The answer should include at least some discussion as to whether a heavily artistic font qualifies for protection.

Bonus if the answer addressed:

  • Separability: If the art can be separated from the typeface/font, it’s copyrightable.
  • Alternatives: Can the font/typeface be protected by other IP protections such as licensing, patents, or trademarks?
  • International implications: Would we expect to see the same results in other jurisdictions?

In answering this question, I expected the LLMs and RAGs to cite:

Benchmarking with the AI models

For this post, I ran my model in the following LLMs/RAGs:

  • Lexis Protégé (work account)
  • Westlaw CoCounsel (work account)
  • ChatGPT o3 deep research (work account)
  • Gemini 2.5 deep research (personal paid account)
  • Perplexity research (personal paid account)
  • DeepSeek R1 (personal free account)
  • Claude 3.7 (personal paid account)

I’ve set up accounts in several commercial GenAI products. Some are free, some are Pro, and Harvard pays for my ChatGPT Enterprise account. As an academic librarian, I have access to CoCounsel and Protétgé.

The individual responses are included in the appendix.

I didn’t have access to Vincent or Paxton at the time. I also didn’t have ChatGPT o3 Pro, either. Later in June, Nick Halperin ran my model in Vincent and Paxton, and I ran the model in o3 Pro. Those examples, as well as GPT5, will be included in the appendix but they are not discussed here.

Bechmarking the results

In parsing the results, most answers were fairly similar with some exceptions:

SourceFont software copyrightableTypefaces/
fonts not copyrightable
Exceptions to font‑software copyrightArt in typefaces/fonts copyrightable
Lexis ProtégéYesYesYesNo
Westlaw CoCounselYesYesNoYes
ChatGPT o3 deep researchYesYesYesYes
Gemini 2.5 deep researchYesYesYesYes
Perplexity researchYesYesYesYes
DeepSeek R1YesYesYesYes
Claude 3.7YesYesYesYes
  • Font software is copyrightable: in all answers 
  • Typefaces/fonts are not copyrightable: in all answers
  • Exceptions to font software copyright: in all answers except Westlaw
  • Art in typefaces/fonts is copyrightable: in all answers except Lexis

Several answers included additional helpful information:

SourceSepera-bilityC Office PoliciesAltern-ativesLicen-singInt’lRecentState law
Lexis ProtégéYesNoNoNoNoNoNo
Westlaw Co-CounselNoNoNoNoNoNoYes
ChatGPT o3 deep researchYesYesYesYesYesYesNo
Gemini 2.5 deep researchYesYesYesYesNoNoNo
Per-
plexity research
YesNoYesNoNoNoNo
Deep-
Seek R1
YesNoYesNoNoNoNo
Claude 3.7NoNoYesYesYesNoNo

  • Discussions about separability: Gemini, ChatGPT, Deep Seek (to some extent), Perplexity, Lexis
  • Specific discussions about Copyright Office policies: Gemini, ChatGPT
  • Discussions about alternatives to copyright (e.g., patent, trademark): Gemini, Claude, ChatGPT, Deep Seek, Perplexity
  • Specific discussions about licensing: Gemini, Claude, ChatGPT
  • International considerations: Claude, ChatGPT
  • Recent developments: ChatGPT
  • State law: Westlaw

The models were somewhat consistent about what they cited:

LLM/RAGCopyright statuteCopyright regsAdobeLaatzShake ShackThe Copyright Compendium
Lexis ProtégéYesYesYesYesNoNo
Westlaw Co-
Counsel
YesYesYesYesYesNo
ChatGPT o3 deep researchYesYesYesNoNoYes
Gemini 2.5 deep researchYesYesYesYesNoYes
Perplexity researchNoYesNoNoNoYes
DeepSeek R1YesYesYesNoNoNo
Claude 3.7NoYesYesNoNoNo
  • The Copyright statute: Lexis, Westlaw, Deep Seek, Chat GPT, Gemini
  • Copyright regs: cited by all
  • Adobe: Lexis, Westlaw, Claude, Deep Seek, Chat GPT, Gemini
  • Laatz: Lexis, Westlaw, Gemini
  • Shake Shack: Westlaw
  • The Copyright Compendium: Perplexity, Chat GPT, Gemini; Lexis cited to Nimmer for the same discussion

The models also included additional resources not on my list:

LLM/RAGBlogs etc.Restat.EltraLaw reviewArticles about loansLibGuides
Lexis ProtégéYesYesYesNoNoNo
Westlaw Co-
Counsel
YesNoNoYesYesNo
ChatGPT o3 deep researchYesNoYesNoNoNo
Gemini 2.5 deep researchYesNoYesNoNoYes
Perplexity researchNoNoNoNoNoNo
DeepSeek R1NoNoYesNoNoNo
Claude 3.7YesNoYesNoNoNo
  • Blogs, websites, news articles: The commercial LLMs.  Gemini found the most, but it’s Google.
  • Restatement: Lexis
  • Eltra Corp. v. Ringer, 1976 U.S. Dist. LEXIS 12611: Lexis, Claude, Deep Seek, Chat GPT, Gemini (t’s not a bad case, but not my favorite for this problem)
  • An actual law review article: Westlaw
  • Higher interest rate consumer loans may snag lenders: Westlaw (not sure why)
  • LibGuides: Gemini
  • Included a handy table: ChatGPT, Gemini

The answers varied in depth of discussion and number of sources:

  • Lexis: 1 page of text, 1 page of sources (I didn’t count the sources in the tabs)
  • Westlaw: 2.5 pages of formatted text, 17 pages of sources
  • ChatGPT: 8 pages of well-formatted text, 1 page of sources
  • Gemini: 6.5 pages of well-formatted text, 1 page of sources
  • Perplexity: A little more than 4 pages of text, about 1 page of sources
  • Deep Seek: a little more than 2 pages of weirdly formatted text, no separate sources
  • Claude: 2.5 pages of well-formatted text, no separate sources

Hallucinations

  • I didn’t find any sources that were completely made up
  • I didn’t find any obvious errors in the written text, though some sources made more sense than others
  • I did not thoroughly examine every source in every list (that would require more time than I’ve already devoted to this blog post). 

Some random concluding thoughts about benchmarking

When I was running these searches, I was sometimes frustrated with the Westlaw and Lexis AI research tools. Not only do they fail to describe exactly what they are searching, they also don’t necessarily capture critical primary sources in their answers (we can get a general idea of the sources used, but not as granular as I’d like). For example, the Copyright Compendium includes one of the more relevant discussions about artistic elements in fonts and typefaces, but that discussion isn’t captured in the RAGs.  To be sure, Lexis did find a similar discussion in Nimmer; Westlaw didn’t find anything comparable, although it did cite secondary sources.

In general, the responses provided by all of the generative AI platforms were correct, but some were more complete than others.  For the most part, the commercial reasoning models (particularly ChatGPT and Gemini) provided more detailed and structured answers than the others.  They also provided responses using formatting designed to make the answers easy to read (Westlaw did as well).

None of the models appeared to consider that recency would be a significant factor in this problem.  Several cited a case from the 70s that didn’t concern fonts.  Several failed to cite Laatz, a recent case that’s on point.  Lexis and Westlaw, of course, cited to authoritative secondary sources (and even a law review article in Westlaw’s case).  The LLMs were less concerned with citing to authority.  In all cases, I would have preferred a more curated set of resources than the platforms provided. 

Finally, none of the platforms included visual elements in what is inherently a visual question. It would have been nice to see some examples of “this is probably copyrightable and this is not” (not that I directly asked for them). 

Coming Soon: The Interactive GenAI Legal Hallucination Tracker — Sneak Peek Today!

If you follow me on LinkedIn or spoke with me at AALL, you’ve probably seen me teasing this project like it’s the season finale of a legal tech drama. Well, the wait is (almost) over — here’s your official sneak peek at our forthcoming interactive GenAI Legal Hallucination Tracker.


The People Behind the Tracker

First, credit where credit is due: fellow law librarian Mary Matuszak, the ultimate sleuth of AI blunders. I’ve sent many curious folks her way on LinkedIn, where she’s been posting hallucinations far more regularly than anyone else. By mid-July, when she sent me this spreadsheet, she’d logged 485 entries — and yes, the number has since blown past 500. She’s basically the Nellie Bly of questionable legal citations.

Next up, my research assistant, Nick Sanctis — the wizard making the interactive tracker happen and gently forcing me to learn just enough R to be dangerous. If there’s a delay, blame my attempts to juggle teaching, running a library, staying current with AI developments, and decoding the mysteries of R this fall.

As for me? I’m the publisher, the cheerleader, and the student in this equation.

The Plan

Today we’re releasing a the basic tracker data in a sortable and searchable table format. In the coming weeks, we’ll roll out the more robust interactive version, followed by new features for viewing, filtering, and analyzing the data — each announced in its own post.

But wait! There’s more! We want you to be part of it! Soon, we’ll be recruiting volunteers to:

  1. Help us find and add more hallucination cases (submission method coming soon)
  2. Analyze the data and share insights with the legal community

If you use the tracker, please cite or link to it in your work. Proper attribution keeps this project alive and growing.

The Data

Announcing the AI Law Librarians Prompt Library

We’re excited to announce a new resource for our community: the AI Law Librarians Prompt Library, a place for law librarians (and the legal community at large) to share and collect useful prompts.

Explore the Prompt Library

Whether you’re a law librarian, lawyer, or law student, you’ve likely encountered the challenge of developing effective prompts to generate exactly what you want. This blog has even covered the topic several times. Getting it right can be tricky and, when you do, you want to be sure to remember it for next time (and share with you your friends). That’s where this library comes in.

Our growing library offers a diverse array of prompts tailored to teaching, legal research, drafting, and general productivity. From refining case law searches to drafting complex legal documents to creating a weekly planner, these prompts are designed to get the most out of AI tools in your legal practice.

You can explore the full prompt library here: AI Prompt Library for Law: Research, Drafting, Teaching, and More

Contribute to the Library

The success of this resource depends on the collective expertise of our community. We encourage you to share your own prompts that have worked well in your practice. Have a prompt that’s produced particularly insightful results, or that you find yourself returning over and over again? Share it with us and help your colleagues enhance their own workflows.

Submit your prompt through our simple form below. Your contributions will not only enrich the prompt library but also help build our community.

A Legal Research Prompting Guide and Generative AI System Comparison Exercise

I’m sharing a guide and exercise I’ve developed for my legal research courses. This Google spreadsheet provides instructions on crafting AI prompts for legal research and includes a practical exercise for comparing different AI systems. It’s designed to help develop skills in leveraging AI for legal research. Feel free to copy it to adapt it to your own purposes. (Note: The images were blurry unless I sort of chopped them off, so sorry about that!)

The spreadsheet consists of three different parts:

Prompt Formulation Guide: This section breaks down the anatomy of an effective legal research prompt. It introduces the RICE framework:

  • R: Role (assigning a role to the AI)
  • I: Instructions (specific tasks for the AI)
  • C: Context (providing necessary background information)
  • E: Expectations (clarifying desired outcomes)

Sample Prompts: The spreadsheet includes several examples of prompts for various legal research scenarios which can serve as templates.

AI System Comparison Exercises: These sections provide a framework for students to test their prompts across different AI systems like Lexis, ChatGPT, and Claude, allowing for a comparative analysis of their effectiveness.

Feel free to copy it to adapt it to your own purposes, and let me know if you have any suggestions for improvements!

AALS Presentation: Improving the Creation of Legal Scholarship with Generative AI

On June 12, 2024, we (Sarah Gotschall, Rebecca Fordon, and Sean Harrington) had the pleasure of presenting Improving the Creation of Legal Scholarship with Generative AI as part of the Association of American Law Schools (AALS) Technology Law section summer webinar series. If interested, you can watch the recording here or access the PowerPoint slides here.

(Oh, and by the way, be sure to register now to see Rebecca Rich and Jennifer Wondracek’s AI and Neurodiverse Students AALS Technology Law section presentation tomorrow, Wednesday, July 10, 2024,  2 p.m. eastern time!)

AI Tools for Scholarly Research

Anway, our presentation focused on the potential of AI in scholarly research, various AI tools with academic uses, and specific use cases for generative AI in legal scholarship. We discussed AI scholarly research tools that connect to databases, use semantic search, and construct answers using generative AI. We also touched upon specialty AI research tools, citation mapping AI, and law-specific scholarly research AI.

It’s important to note that many of the specialty AI systems, such as Consensus, Litmaps, and Elicit, currently have limited coverage of legal literature, particularly law review articles. As a result, these tools may be more useful for legal scholars conducting interdisciplinary research that draws upon sources from other fields. However, we are hopeful that these systems will expand their databases to include more legal literature in the future, making them even more valuable for legal scholarship.

Specific AI Systems for Interdisciplinary Researchers

During the presentation, we delved into several specific AI systems that can be particularly useful for interdisciplinary reseachers:

  1. Consensus ($9/mo, with a more limited free version): A tool that connects to databases of academic research and uses generative AI to construct answers to queries.
  2. Litmaps ($10/mo, with a limited free version to test): A citation mapping AI that allows users to select or upload papers and find related papers within the same citation network, facilitating discovery and pattern identification.
  3. Elicit ($10/mo): An AI research tool that combines semantic search and generative AI to help researchers locate relevant information and generate insights.

We also covered other noteworthy tools such as Scite Assistant ($20/mo), Semantic Scholar (free), Research GPT, Scholar GPT, Connected Papers ($6/mo), Research Rabbit (free), Inciteful (free), and more. These tools offer a range of features, from citation mapping to literature review assistance, making them valuable additions to a legal scholar’s toolkit.

General-Purpose AI Systems

In addition to these specialized tools, we discussed the potential of general-purpose AI systems like ChatGPT, Claude, and Perplexity AI for legal academic research and writing. These powerful language models can assist with various tasks, such as generating ideas, summarizing documents, and even drafting sections of papers. However, we emphasized the importance of using these tools responsibly and critically evaluating their output.

Custom GPTs

Another exciting development we covered was the creation of custom GPTs, or user-created versions of ChatGPT tailored to specific tasks. By providing a custom GPT with relevant documents and instructions, legal scholars can create powerful tools for their research and writing needs. We outlined a simple four-step process for building a custom GPT: creating instructions in a well-organized document, converting it to markdown, uploading relevant documents as a knowledge base, and determining the desired features (e.g., web browsing, image generation, or data analysis).

Use Cases for Generative AI in Legal Scholarship

Throughout the presentation, we explored several use cases for generative AI in legal scholarship, including targeted research and information retrieval, document summaries, analysis and synthesis, outlining, idea generation and brainstorming, drafting, and proofreading.

Important Considerations

We also addressed important considerations when using AI in academic work, such as citing AI-generated ideas, the implications of AI-generated content in scholarship, and the need for guidelines from industry groups and publishers. To provide context, we shared a list of articles discussing AI and legal scholarship and resources for learning more about using AI for legal scholarship.

Conclusion

Our presentation concluded by highlighting the potential of generative AI to assist in various aspects of legal scholarship while emphasizing the importance of ethical considerations and proper citation practices.

Other Info:

Resources to Learn More About Using AI for Legal Scholarship

  • Georgetown University Law Library AI Tools Guide: Provides resources and information on various AI tools that can assist in research and scholarship. It includes descriptions of tools, ethical considerations, and practical tips for effectively incorporating AI into academic work.
  • University of Washington Law Library Writing for and Publishing in Law Reviews: Provides resources and guidelines on using AI tools ethically in legal writing, including how to cite AI, maintain academic integrity, and the impact of AI on scholarly publishing.
  • Citing Generative AI: Provides Bluebook advice on citing AI 
  • Andy Stapleton – YouTube: Videos provide tips and advice for researchers, students, and academics about how to use general GAI and specialty academic GAI for academic writing. 
  • Mushtaq Bilal – Twitter: Provides tips and resources for researchers and academics, particularly on how to improve their writing and publishing processes using GAI.
  • Dr Lyndon Walker: Offers educational content on statistics, research methods, and data analysis, and explores the application of GAI in these areas
  • Legal Tech Trends – Substack: Covers the latest trends and developments in legal technology and provides insights into how GAI is transforming the legal industry, including tools, software, and innovative practices.

Articles About AI and Legal Scholarship

  • Will Machines Replace Us? Machine-Authored Texts and the Future of Scholarship, Benjamin Alarie, Arthur Cockfield, and GPT-3, Law, Technology and Humans, November 8, 2021. First AI generated law review article! It discusses the capabilities and limitations of GPT-3 in generating scholarly texts, questioning the future role of AI in legal scholarship and whether future advancements could potentially replace human authors.
  • A Human Being Wrote This Law Review Article: GPT-3 and the Practice of Law, Amy B. Cyphert, UC Davis Law Review, November 2021. This article examines the ethical implications of using GPT-3 in legal practice, highlighting its potential benefits and risks, and proposing amendments to the Model Rules of Professional Conduct to address AI’s integration into the legal field.
  • The Implications of ChatGPT for Legal Services and Society, Andrew M. Perlman, Suffolk University Law School, December 5, 2022. This paper, generated by ChatGPT-3.5 after it was first introduced, explores the sophisticated capabilities of AI in legal services, discussing its potential regulatory and ethical implications, its transformative impact on legal practices and society, and the imminent disruptions AI poses to traditional knowledge work.
  • Using Artificial Intelligence in the Law Review Submissions Process, Brenda M. Simon, California Western School of Law, November 2022. This article explores the potential benefits and drawbacks of implementing AI in the law review submissions process, emphasizing its ability to enhance efficiency and reduce biases, while also highlighting concerns regarding the perpetuation of existing biases and the need for careful oversight.
  • Is Artificial Intelligence Capable of Writing a Law Journal Article?, Roman M. Yankovskiy, Zakon (The Statute), Written: March 8, 2023; Posted: June 20, 2023, This article explores AI’s potential to create legal articles, examining its ability to handle legal terminology and argumentation, potential inaccuracies, copyright implications, and future prospects for AI in legal practice and research.
  • Should Using an AI Text Generator to Produce Academic Writing Be Plagiarism?, Brian L. Frye and Chat GPT, Fordham Intellectual Property, Media & Entertainment Law Journal, 2023. This article provocatively addresses whether using AI text generators like ChatGPT to produce academic writing constitutes plagiarism, exploring the implications for originality, authorship, and the nature of scholarship in the digital age.
  • Move Over Law Professors? AI Likes to Write Law Review Articles Too!, Sarah Gotschall, AI Law Librarians, March 28, 2024. This blog post examines the capabilities of the AI text generator Claude 3 in producing a law review article (Bloodlines Over Merits: Exposing the Discriminatory Impact of Legacy Preferences in College Admissions, Claudia Trey, SSRN, April 12, 2024), discussing its ability to generate well-written content with footnotes, the challenges encountered, and the potential future impact of AI on academic writing.